OCR COMPTA : Extraction of invoice data
MBH OCR is an intelligent document processing solution that automatically extracts accounting data from scanned documents, invoices, and workbooks, streamlining financial workflows and improving accuracy.
Présentation du projet
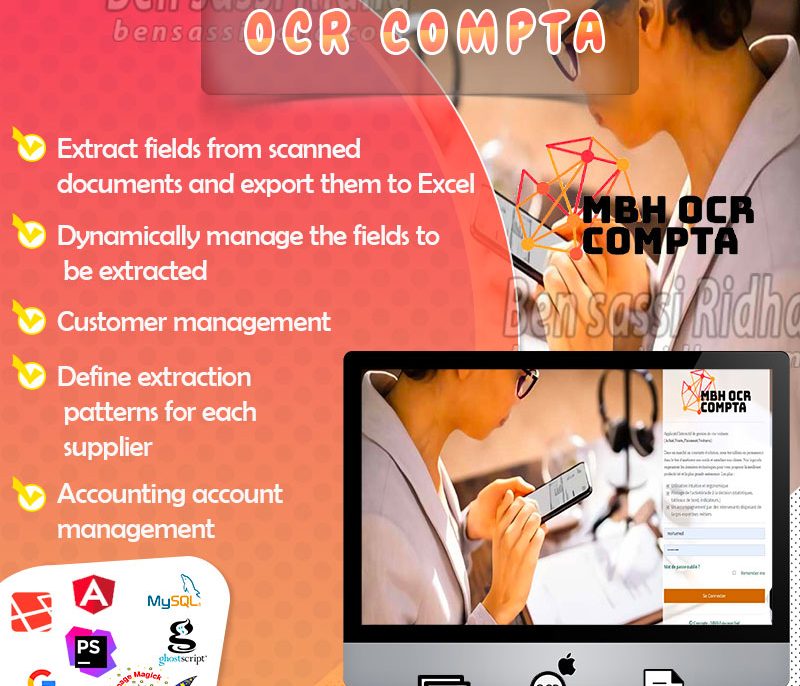
OCR COMPTA – This web application dedicated to accountants aims to save time in processing invoice binders. It permits :
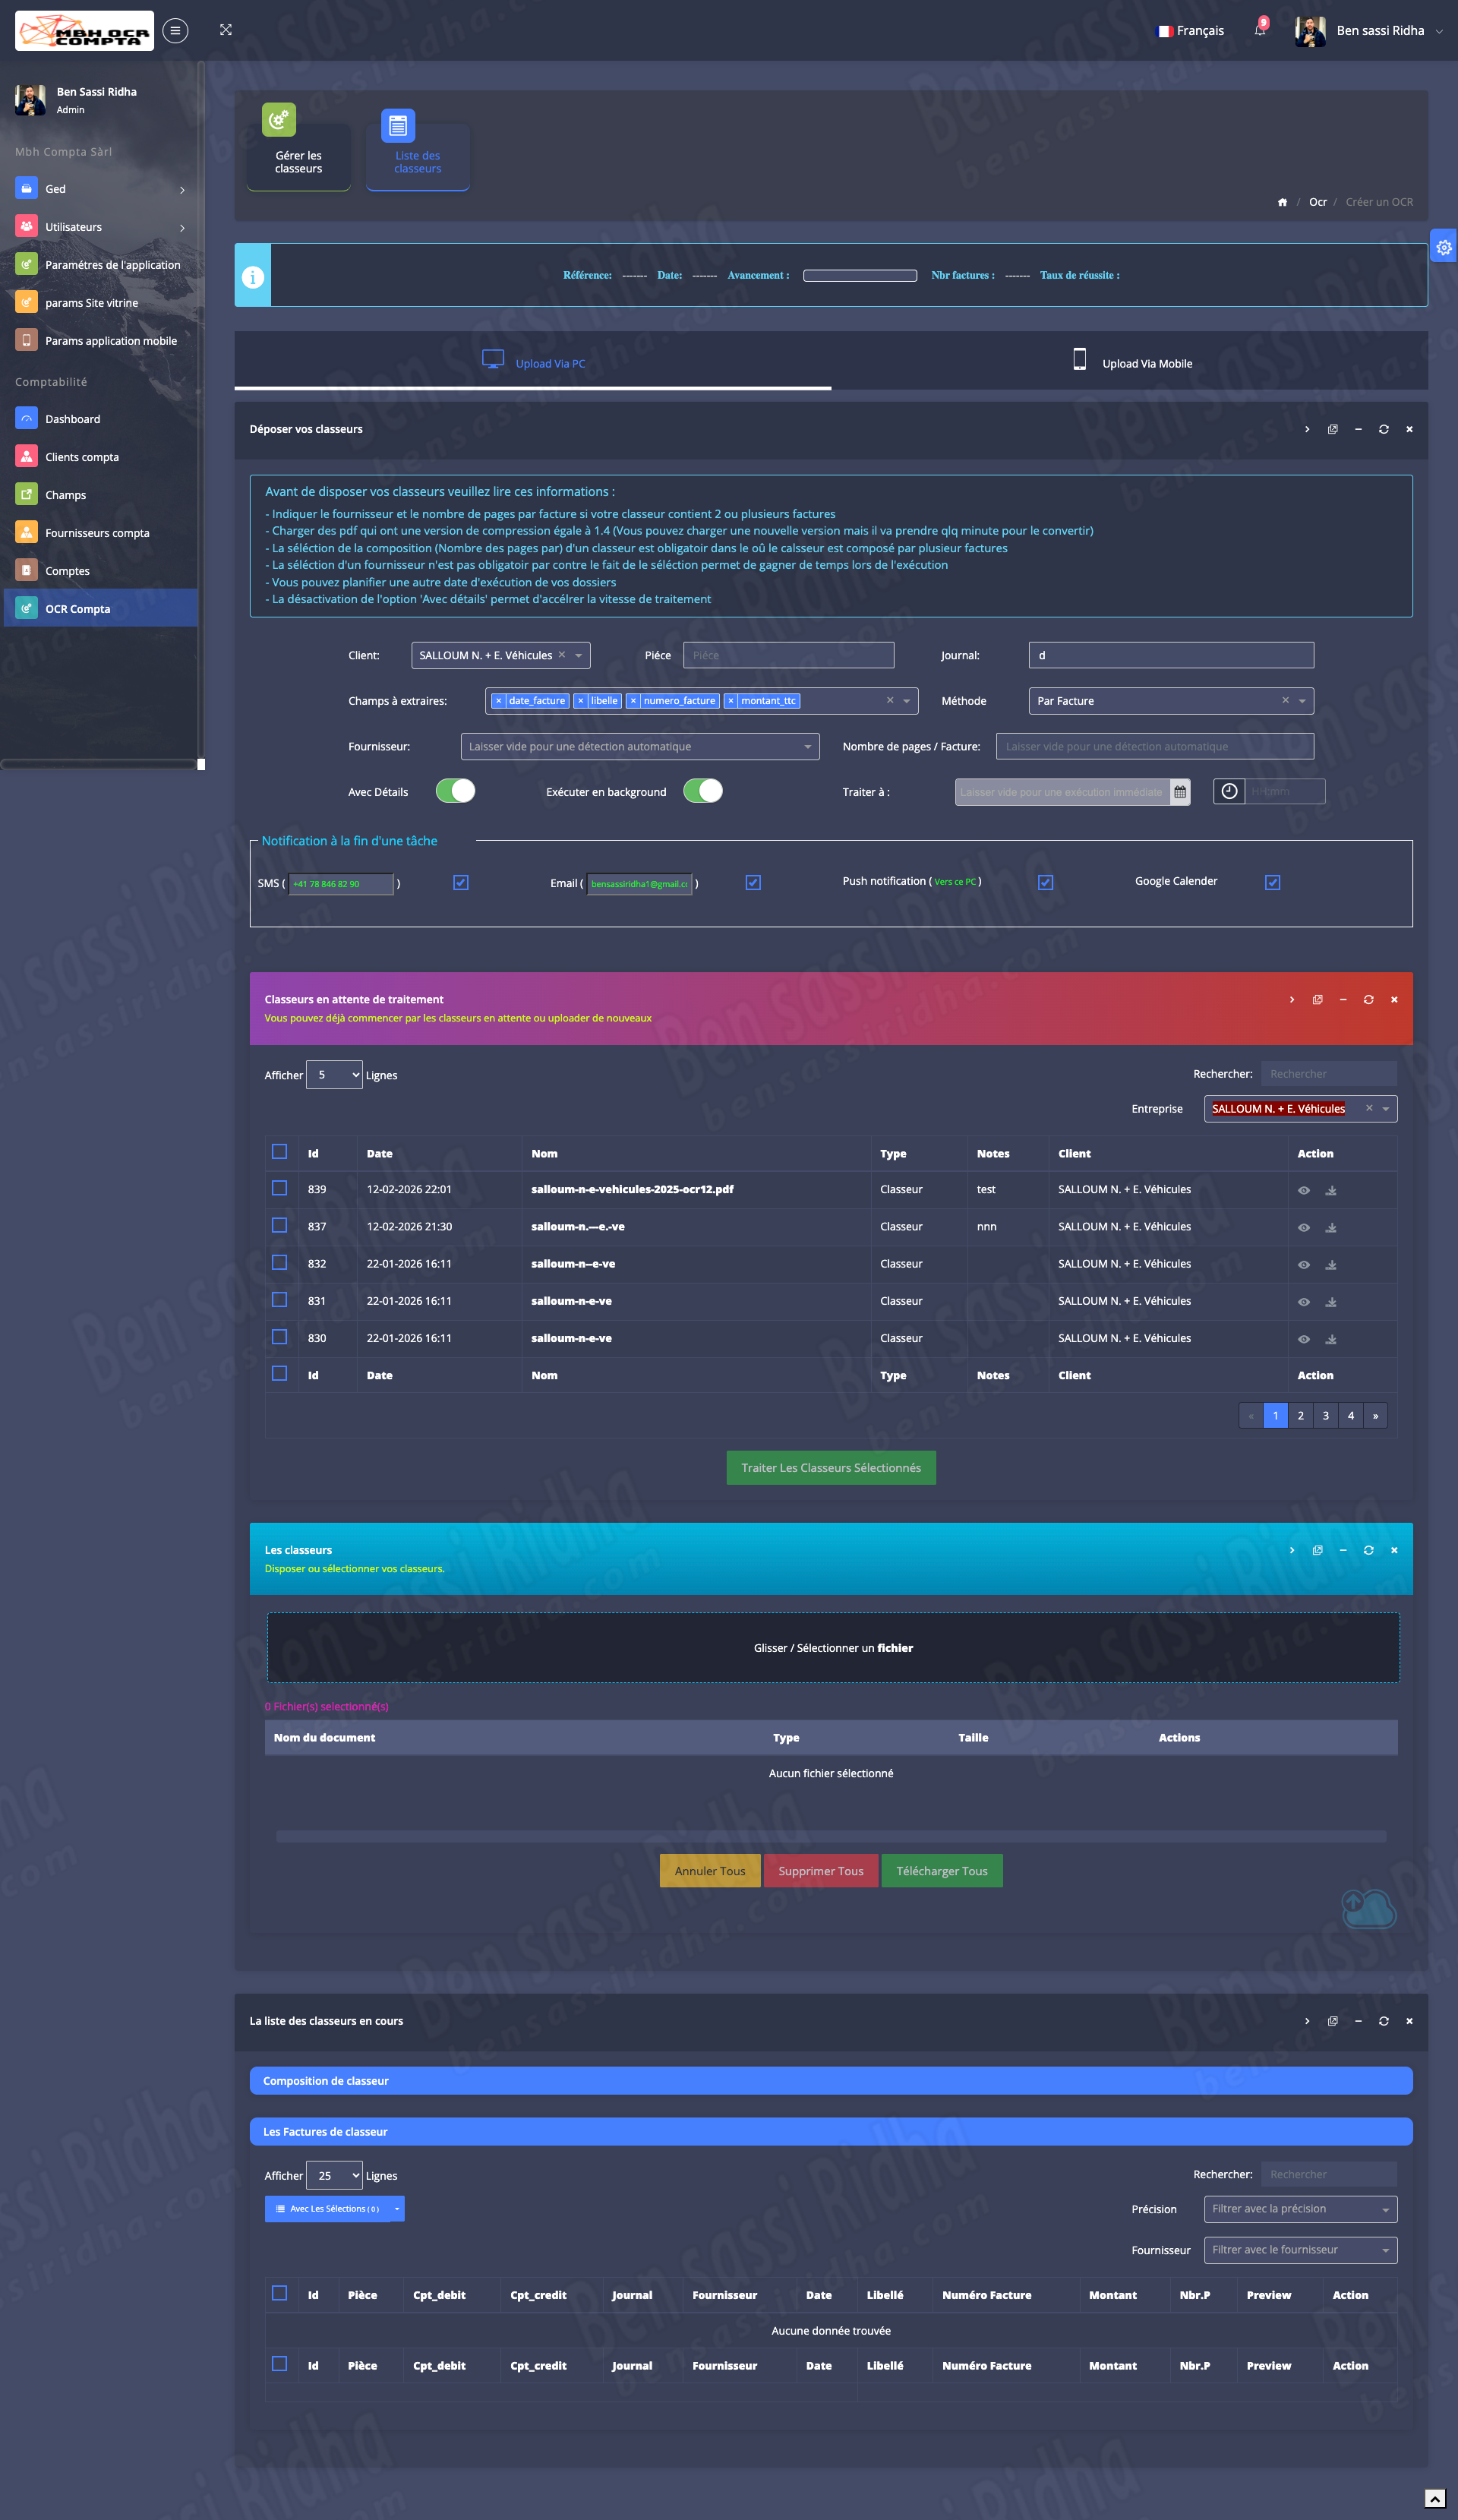
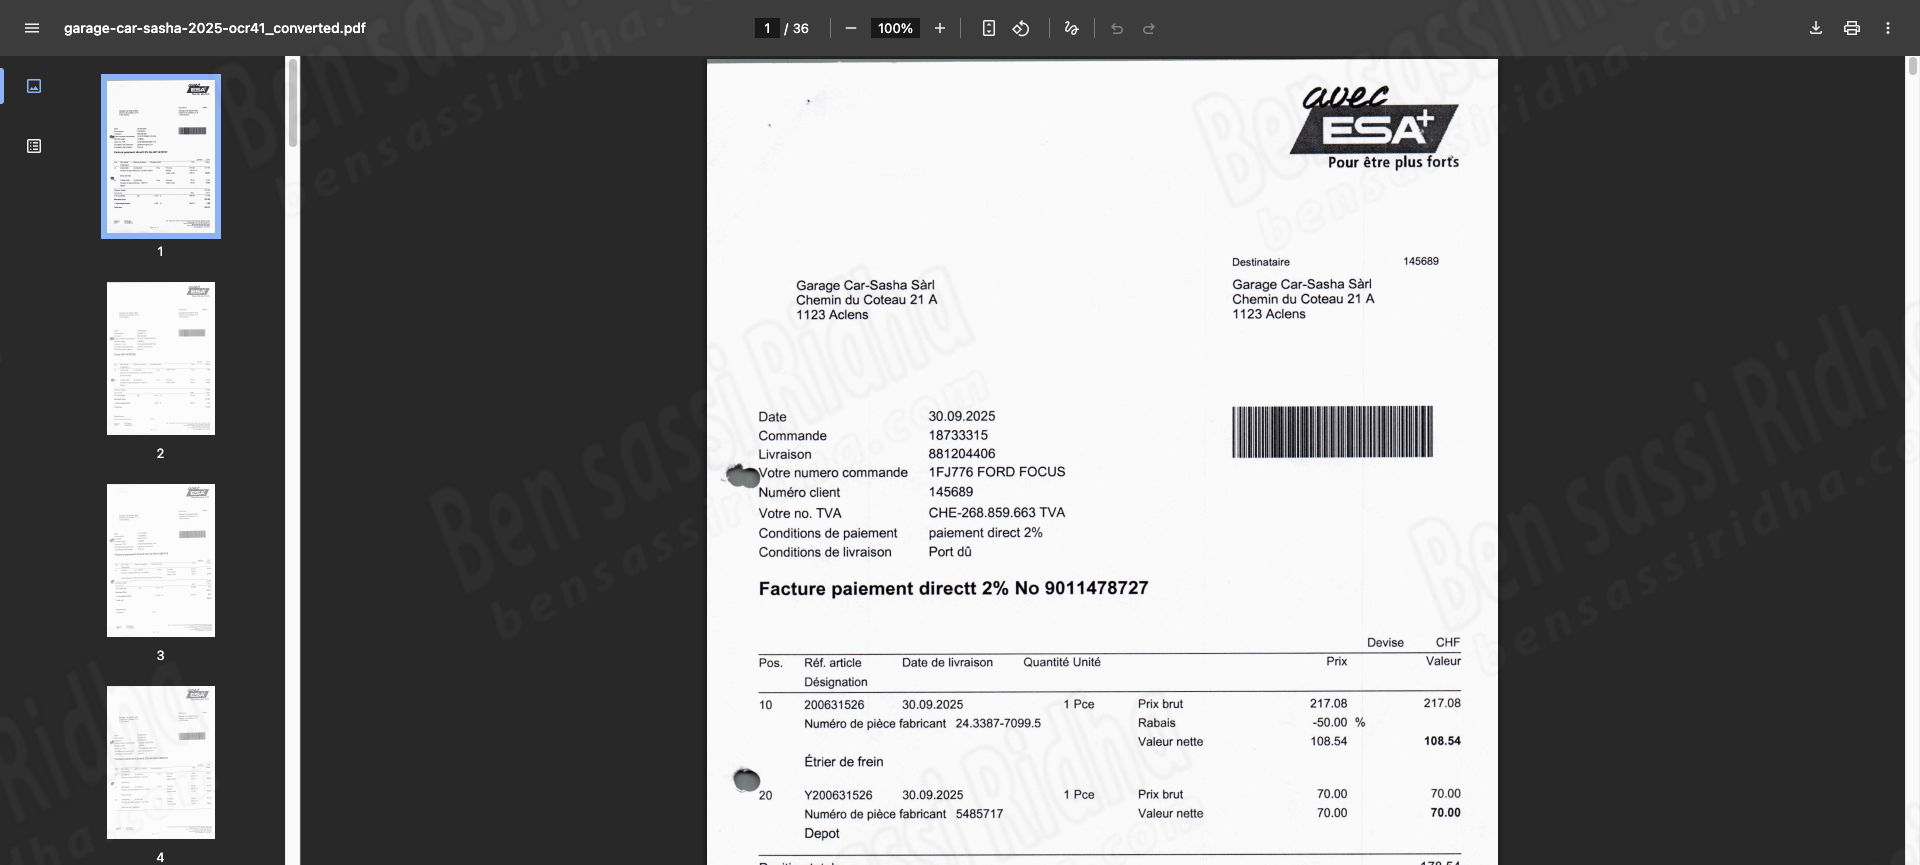
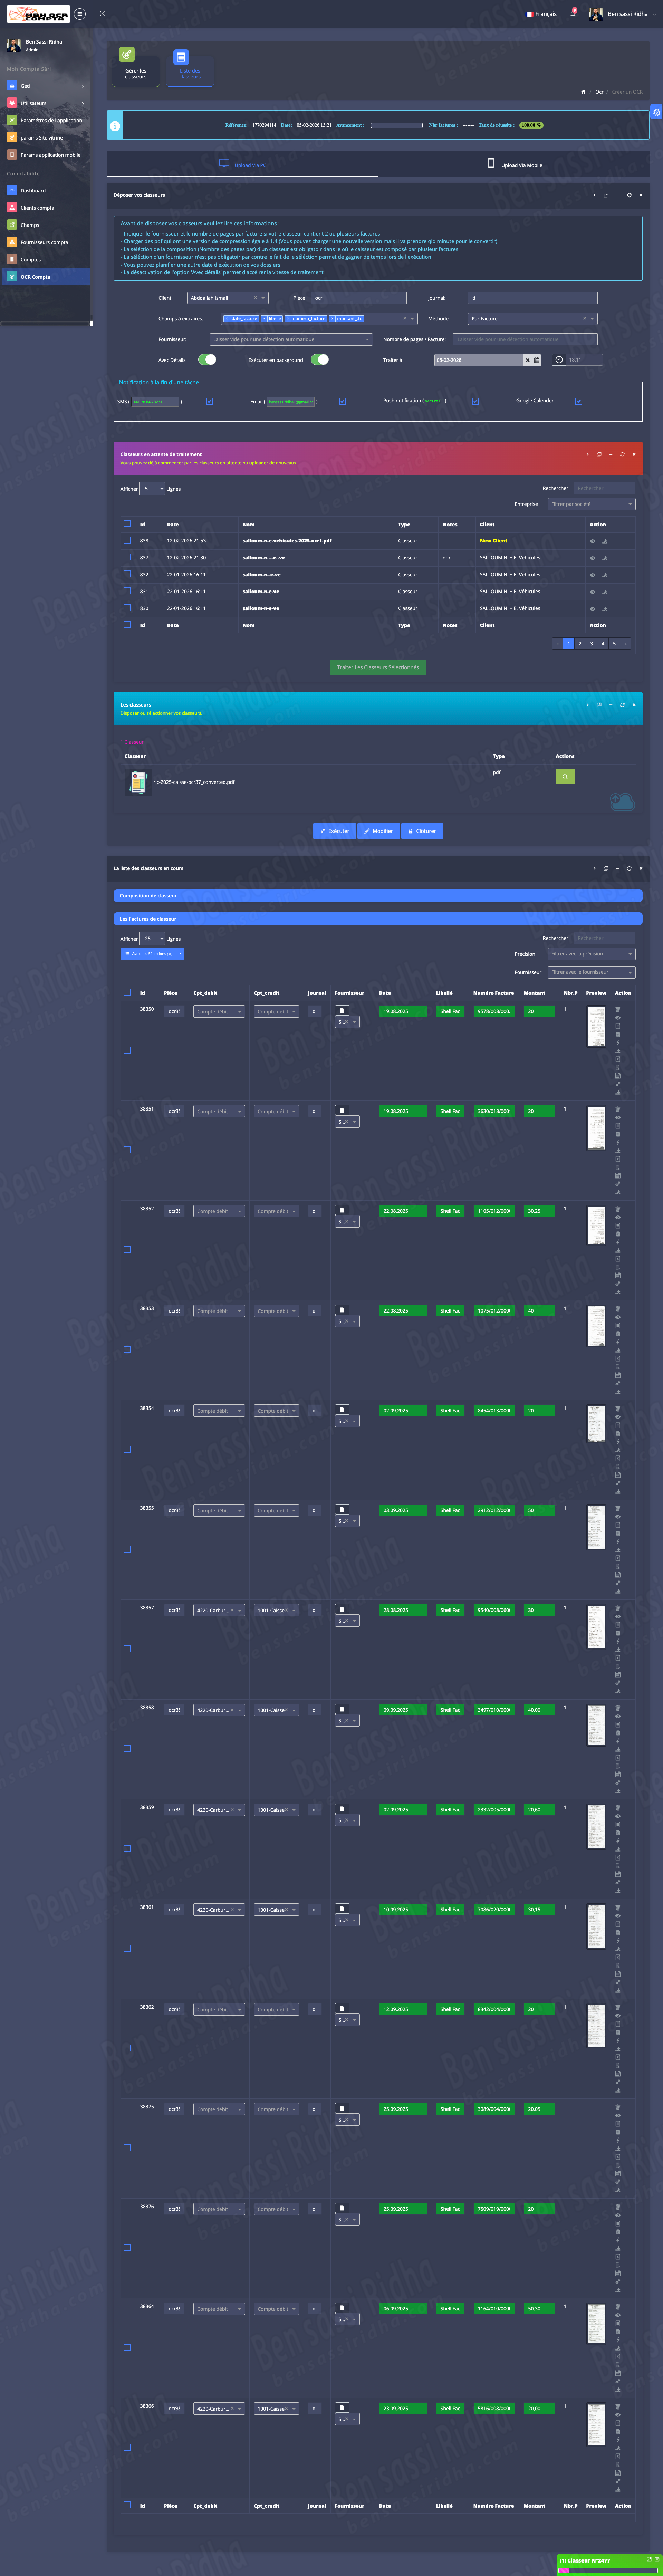
- Extraction of fields (e.g. VAT, Amount including tax, invoice number, etc.) quickly from invoices in image or PDF format
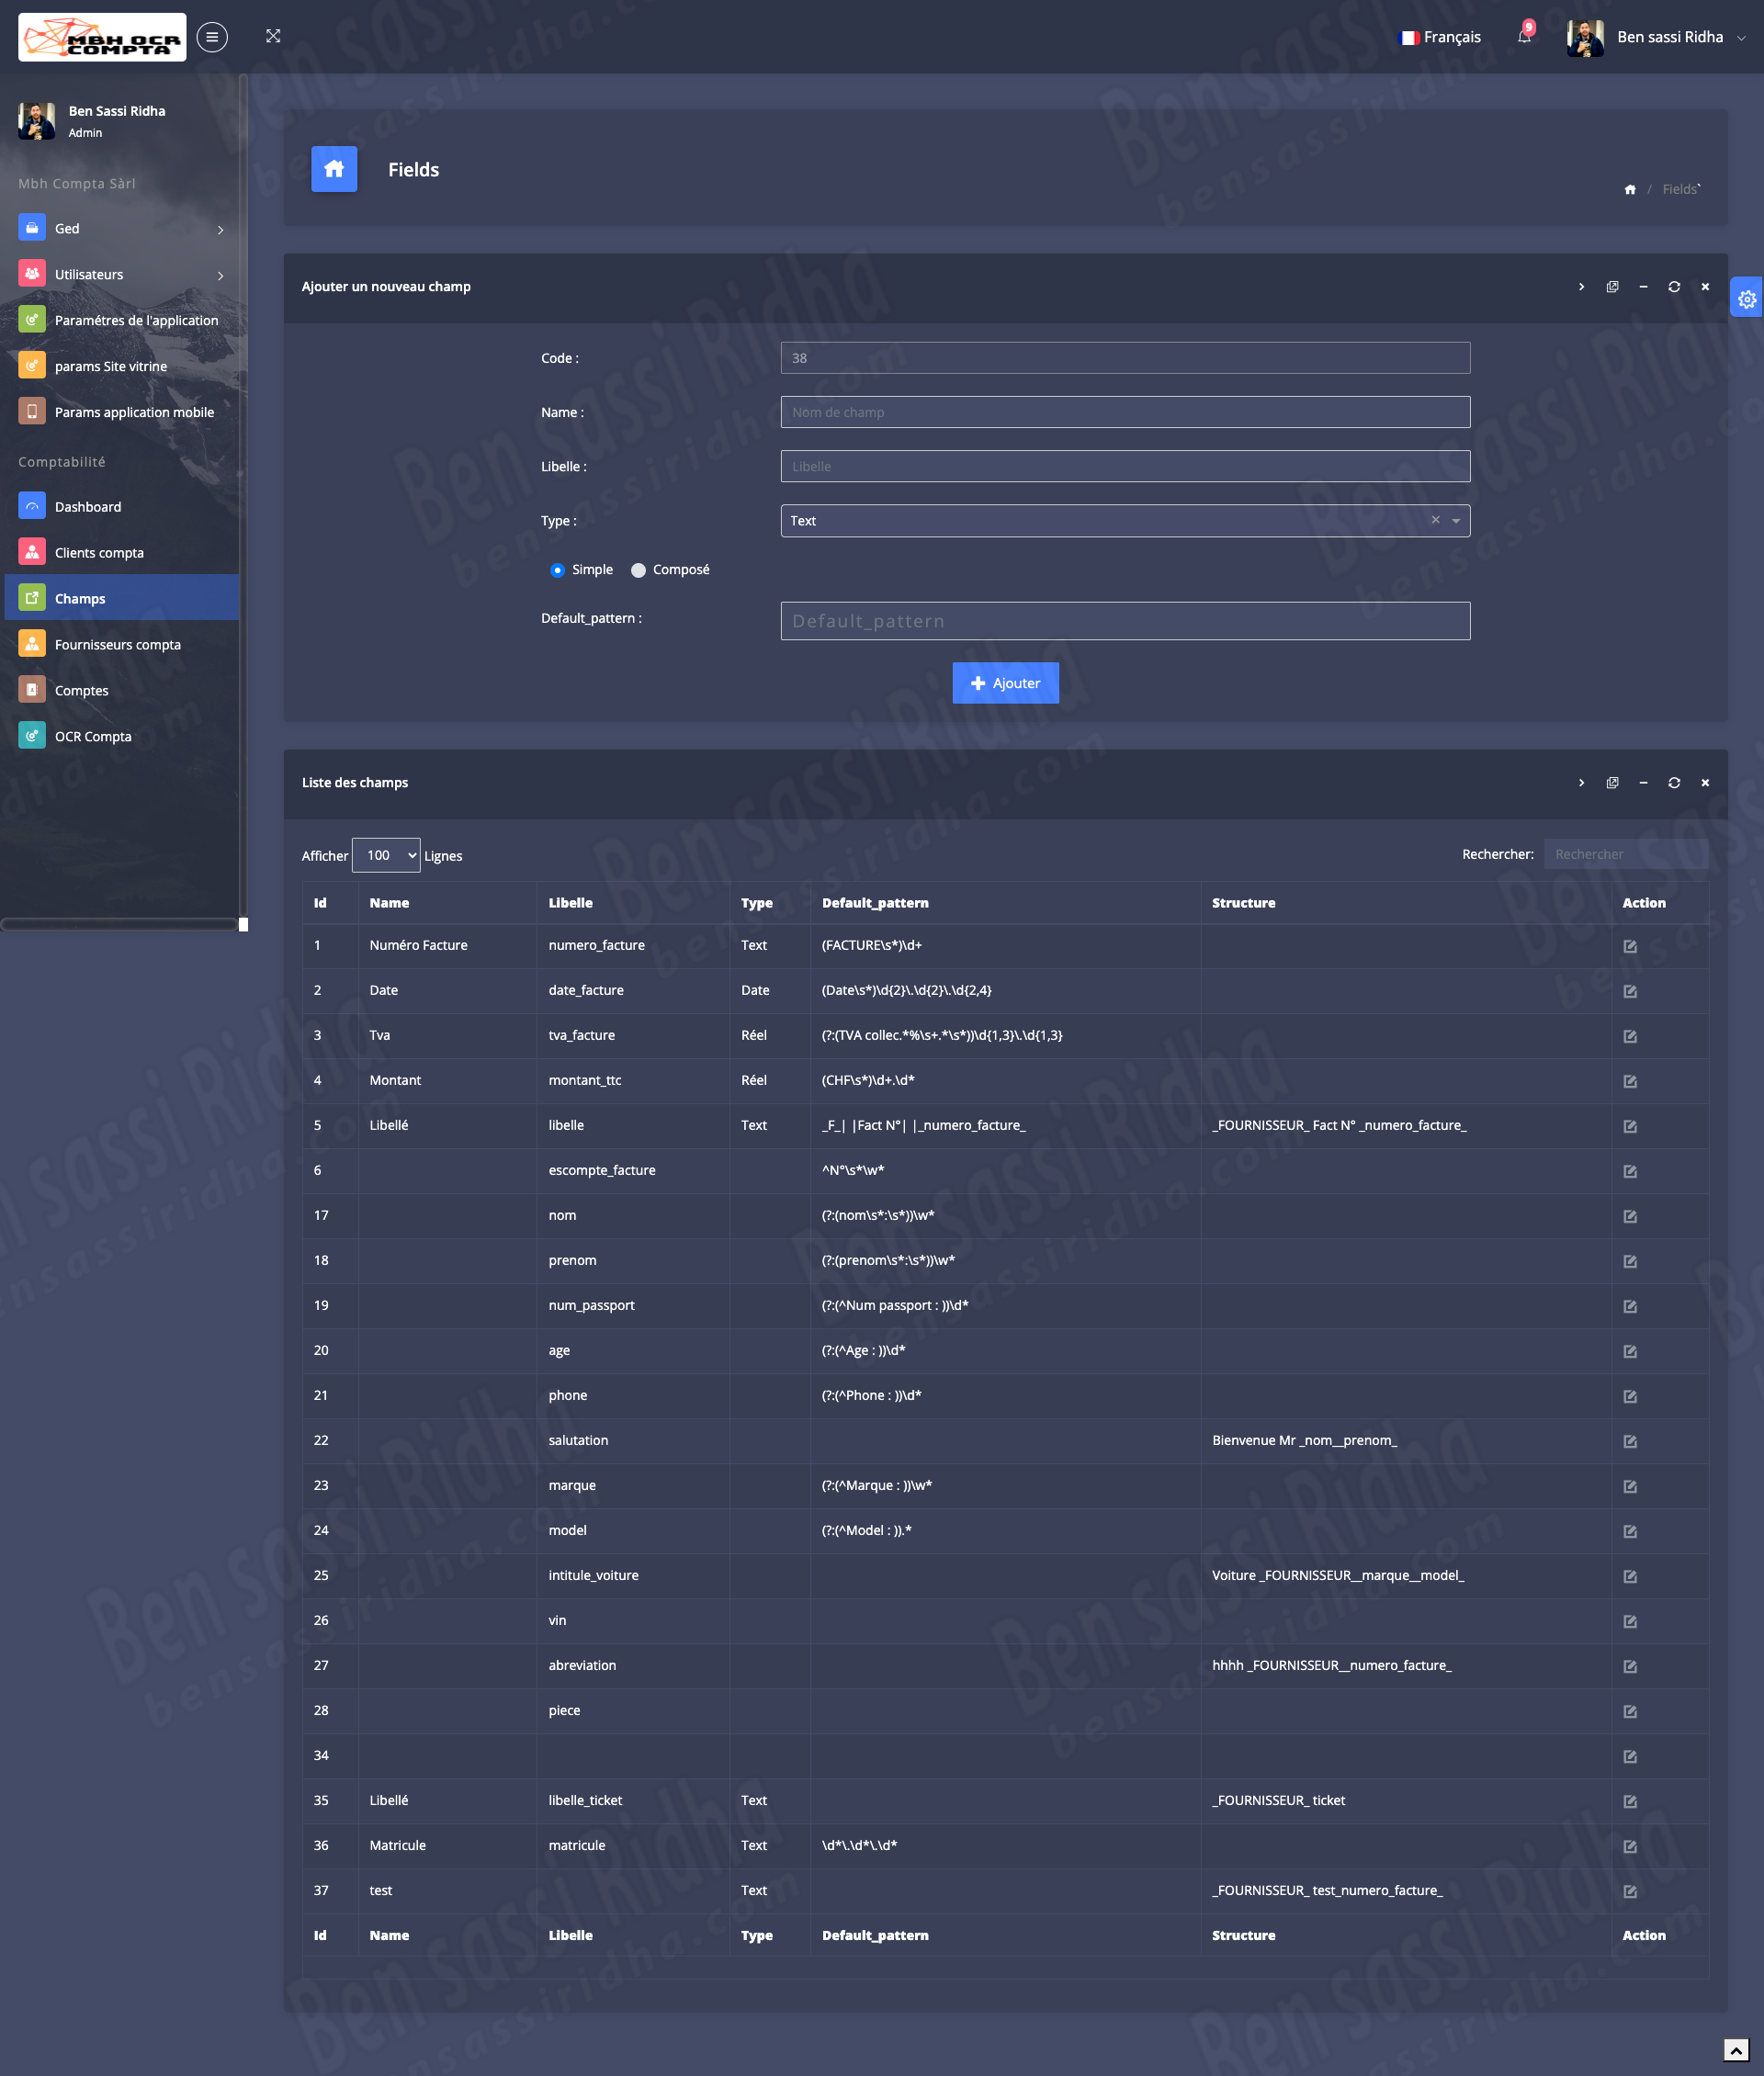
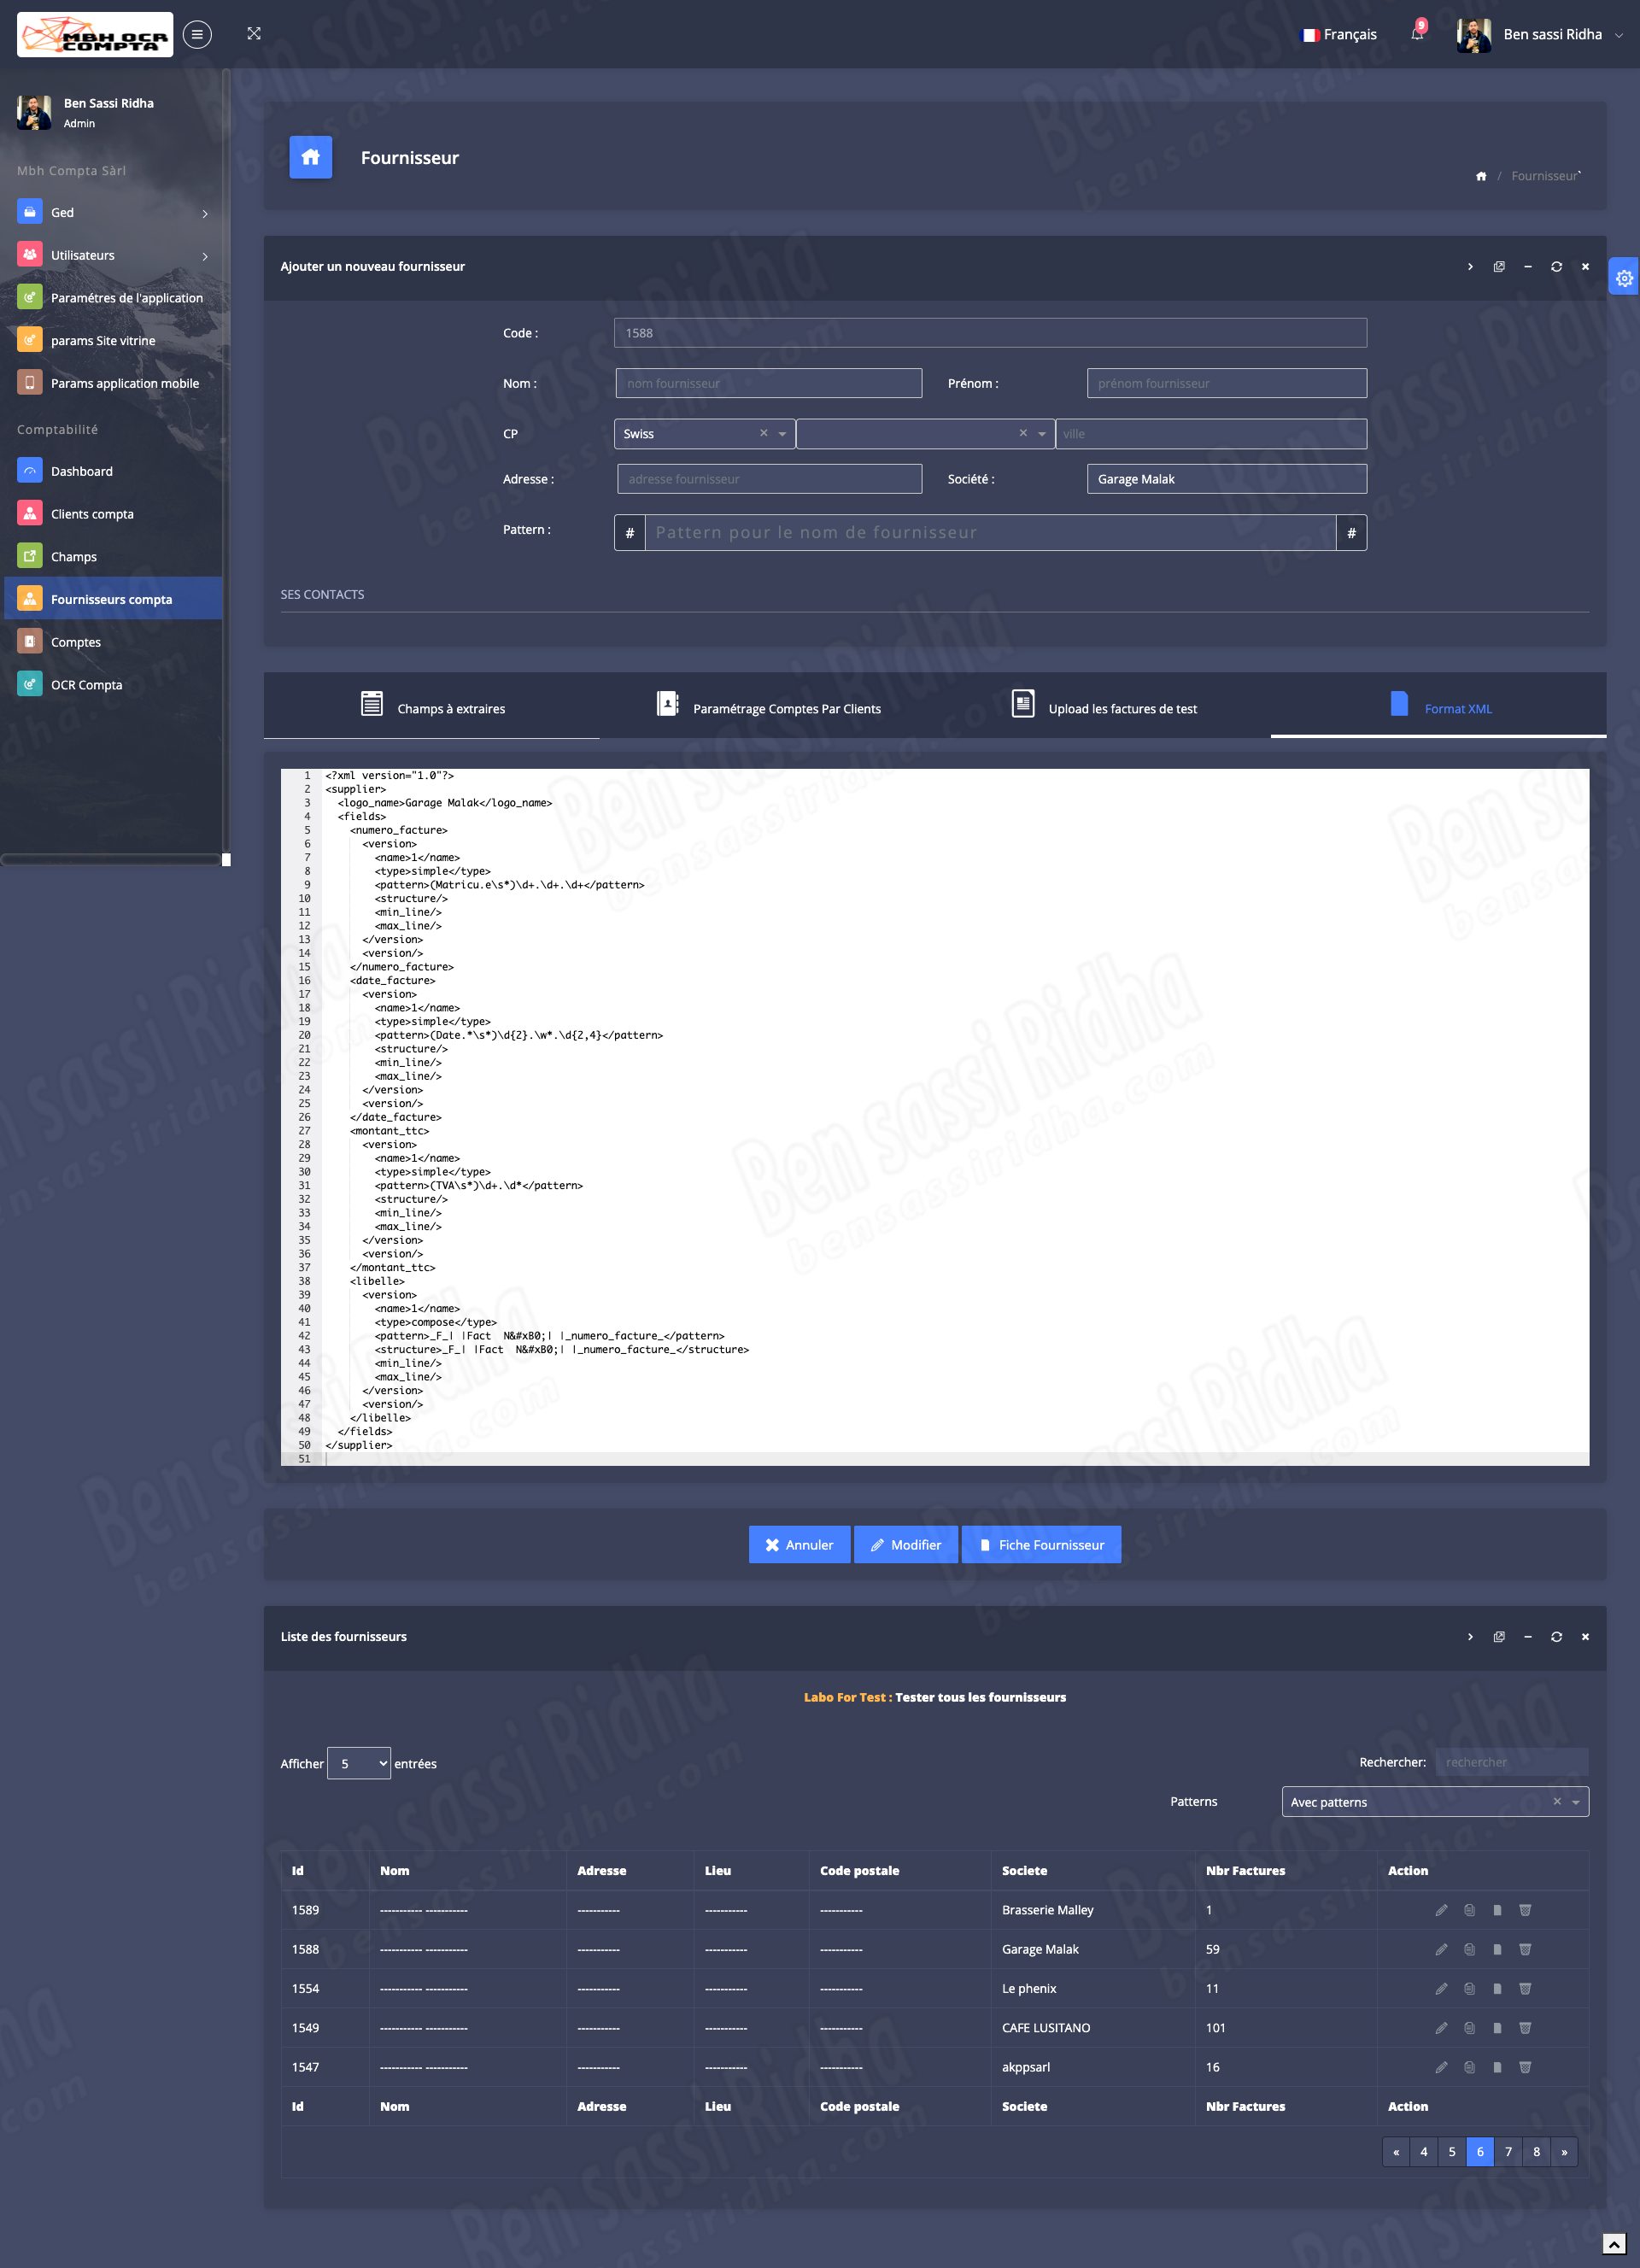
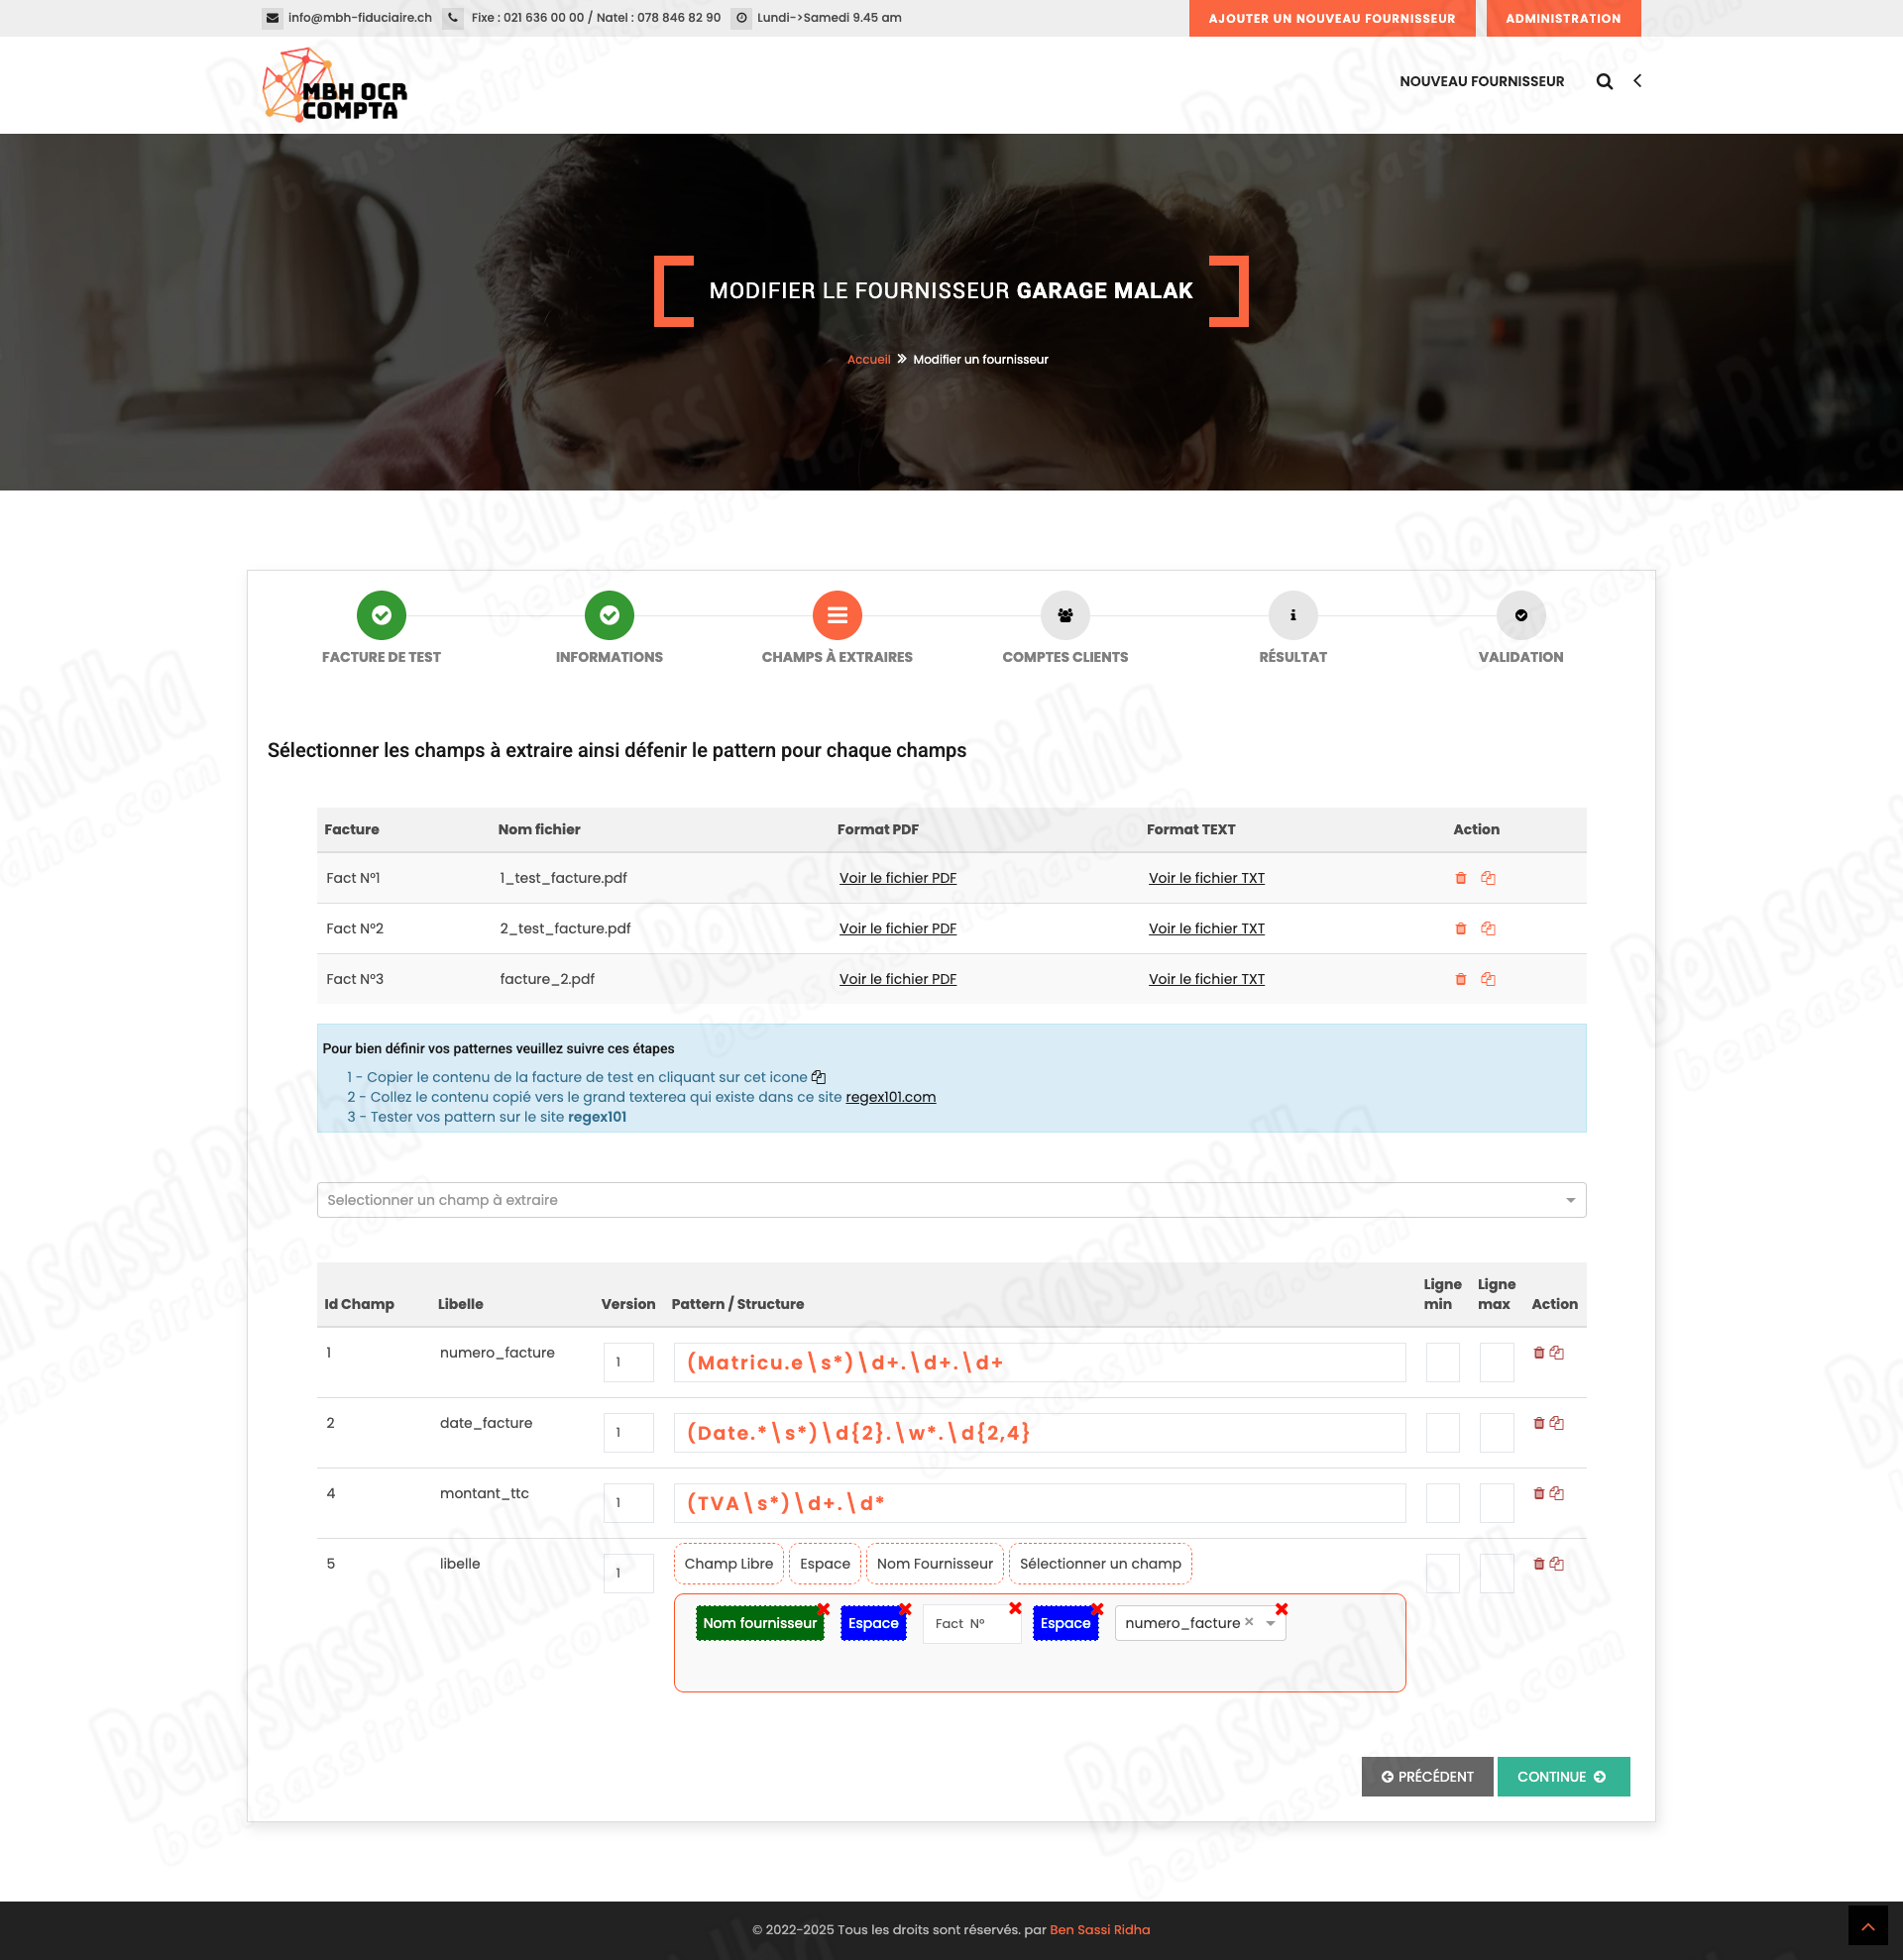
- Dynamic management of fields to extract and their patterns
- Manage the possibility of having several versions for each field
- Manage simple fields and compound fields which are composed of other fields (e.g.; label = No. numFactSupplierName)
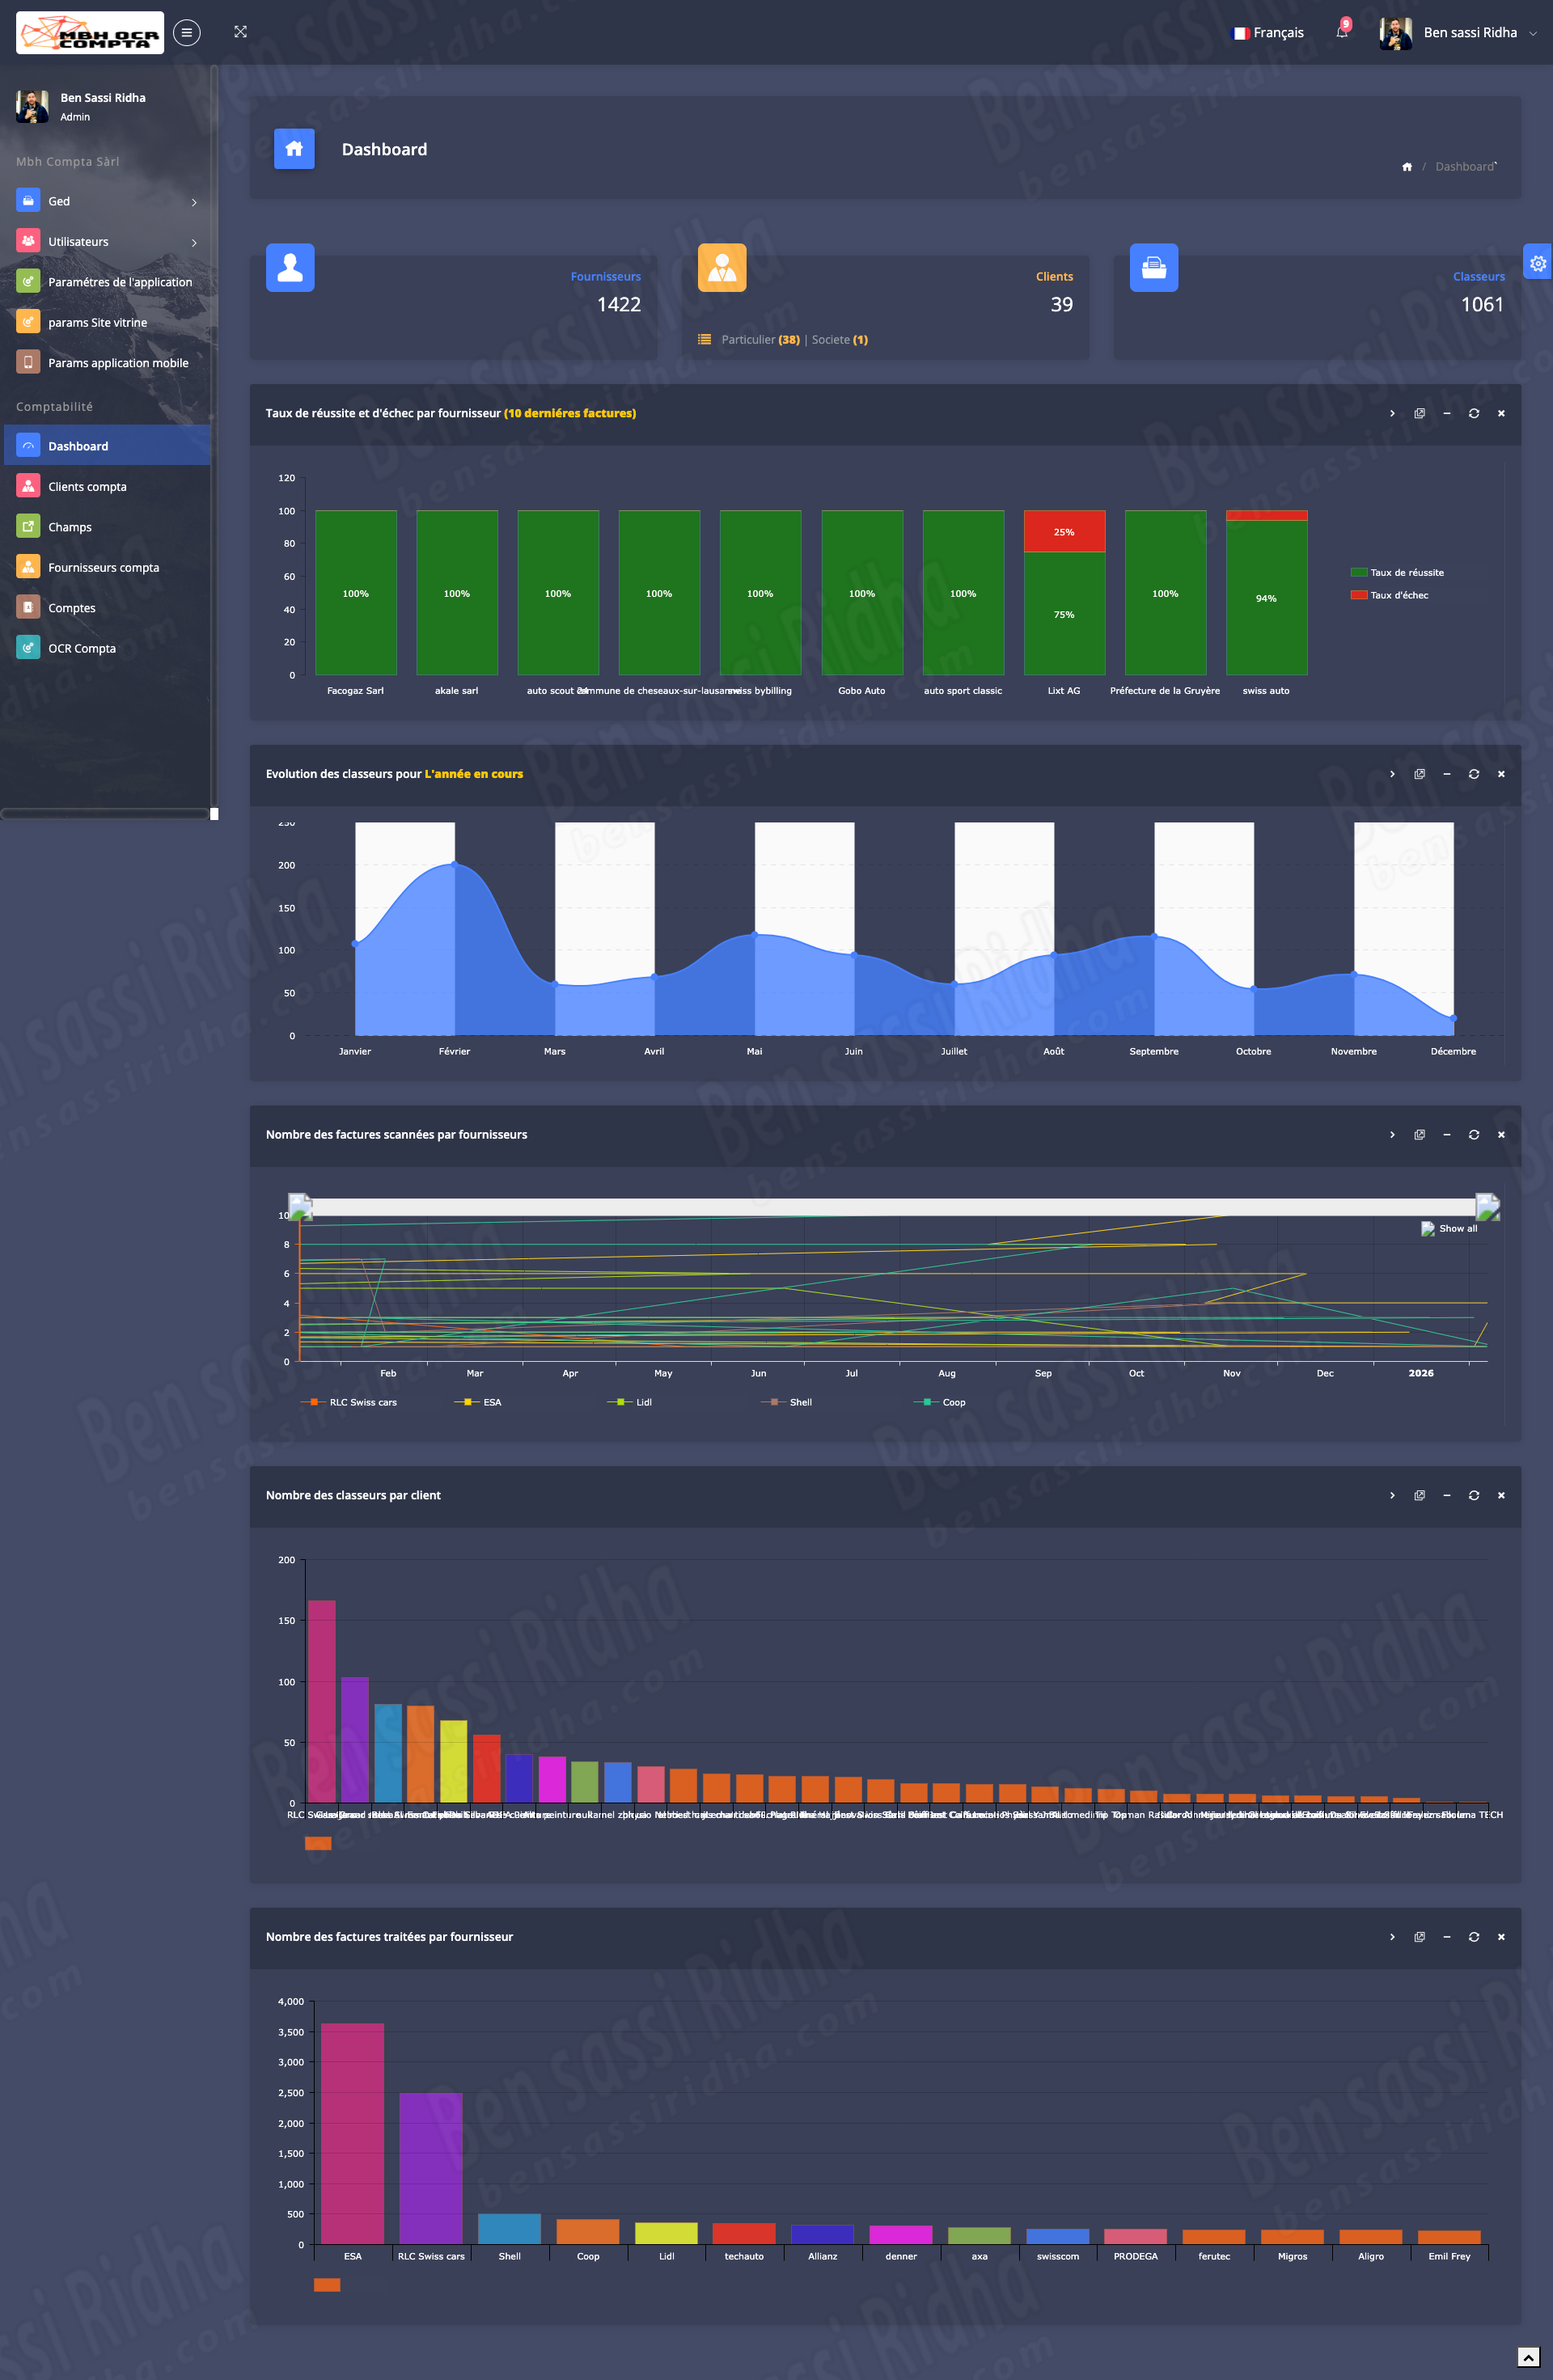
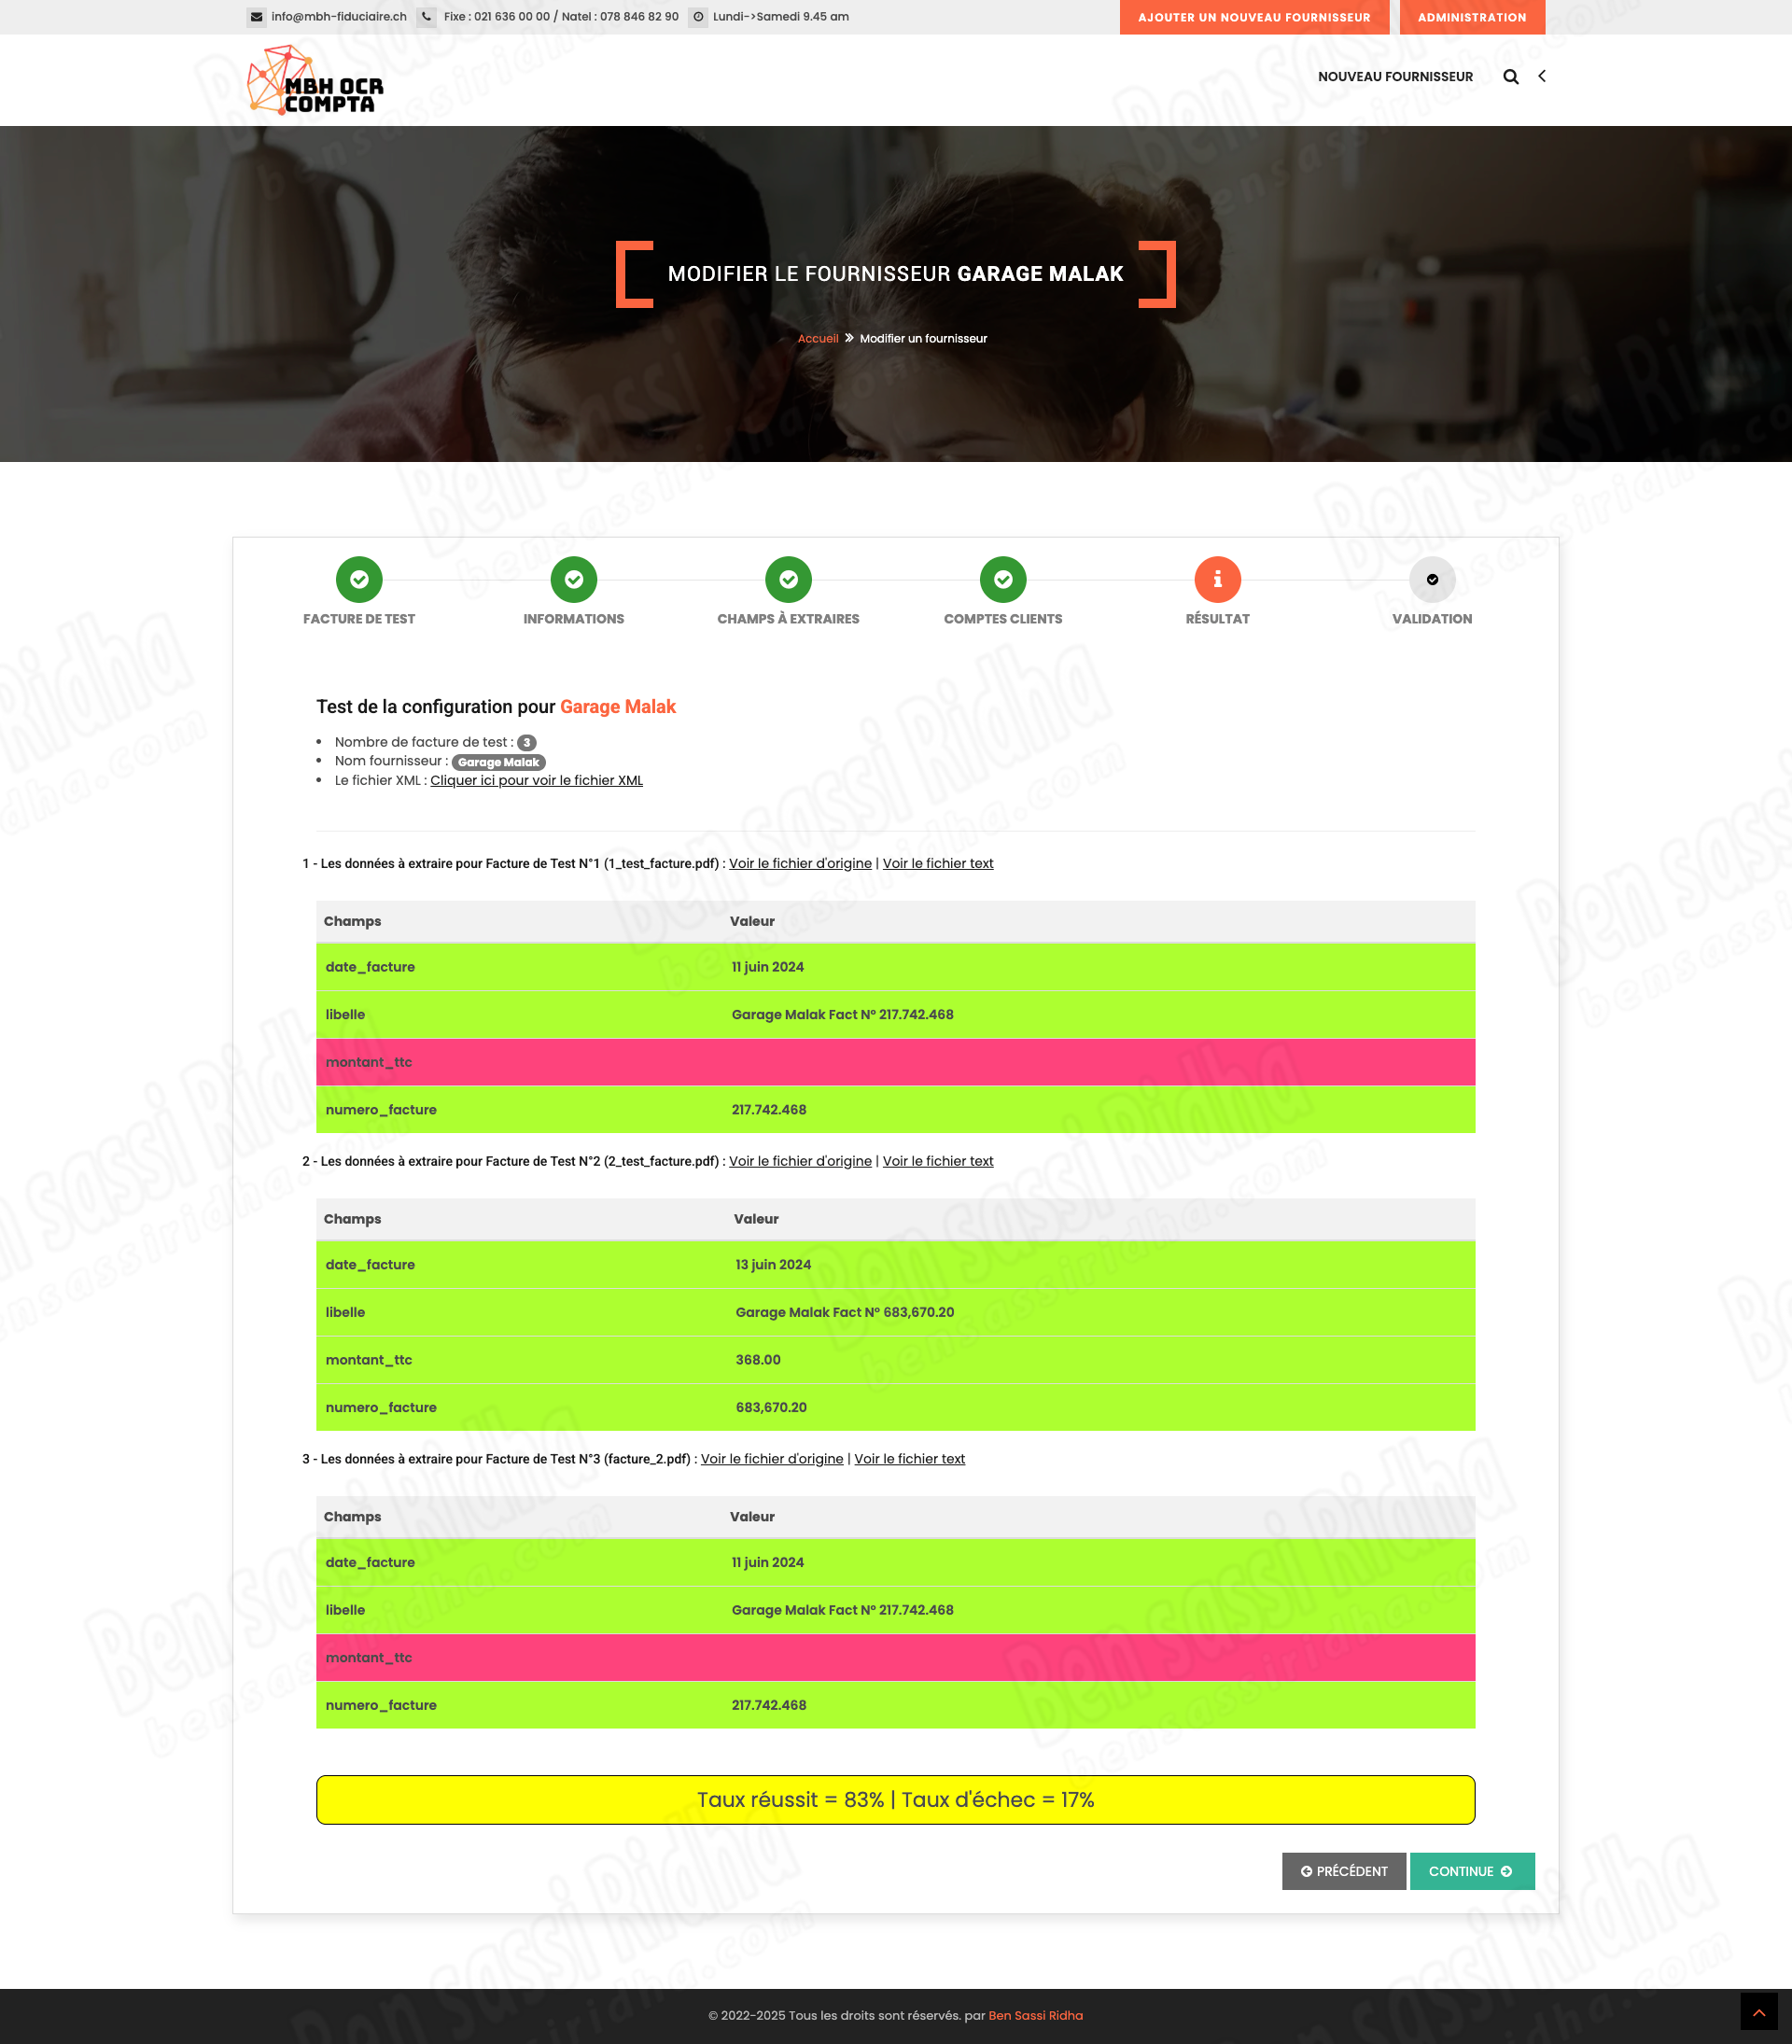
- View key figures such as field detection success and failure rates for each supplier
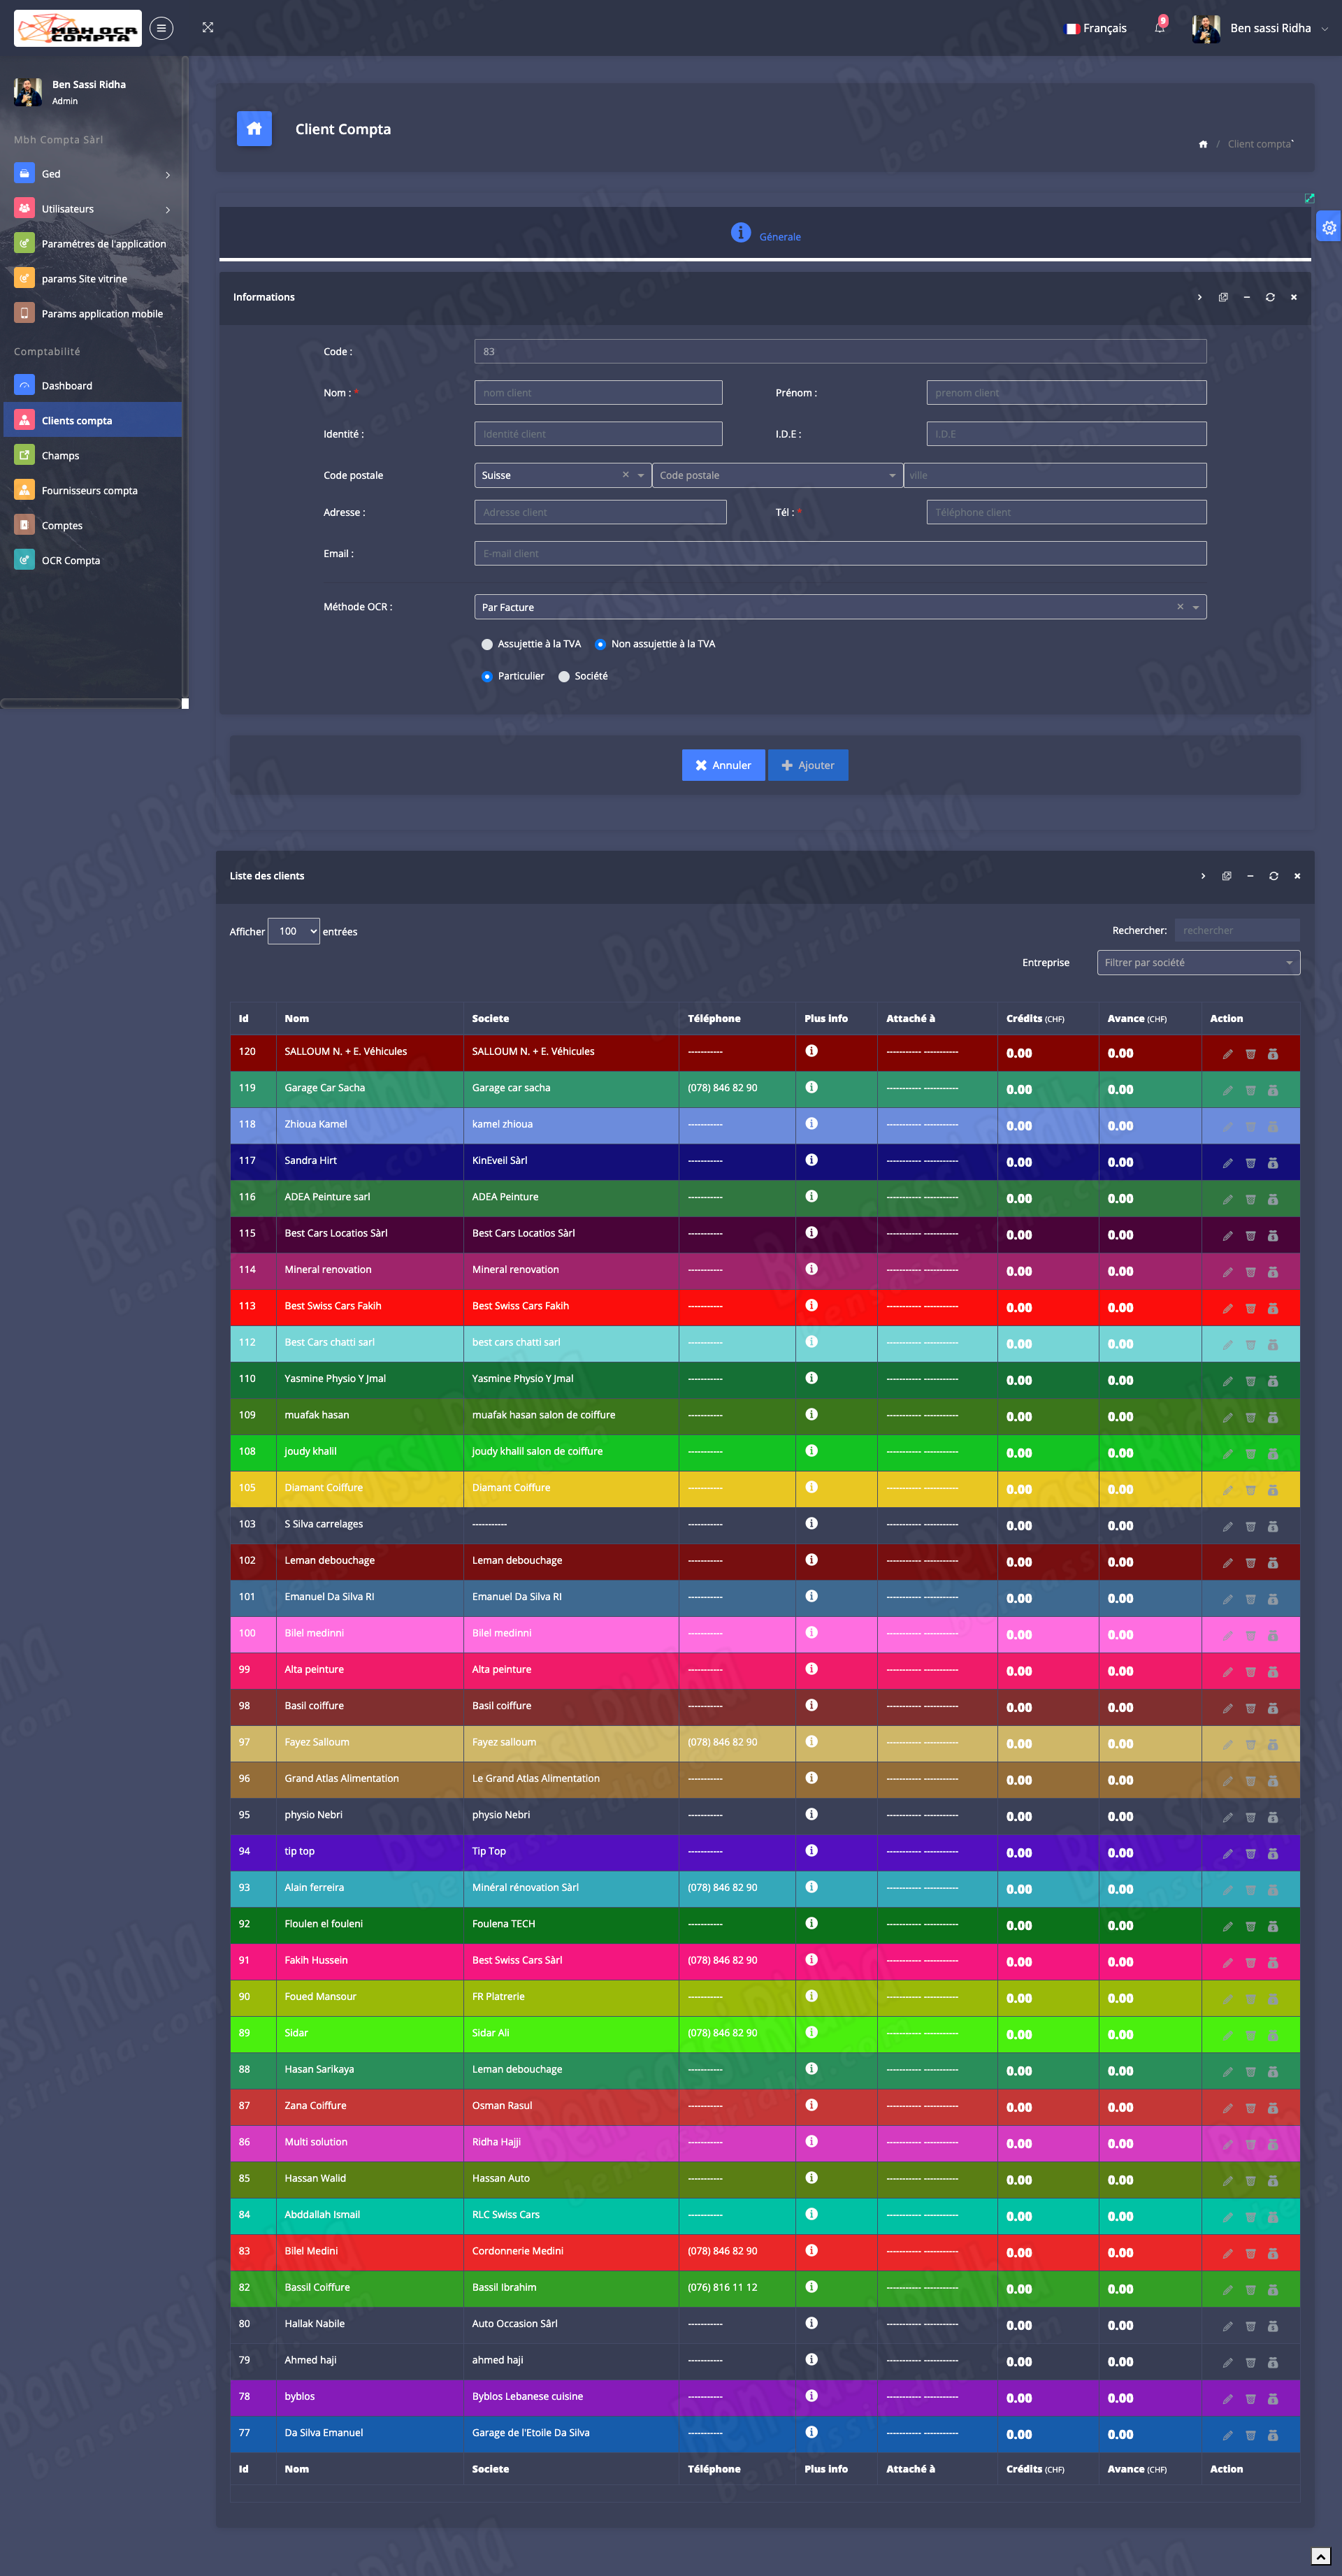
- Manage customers
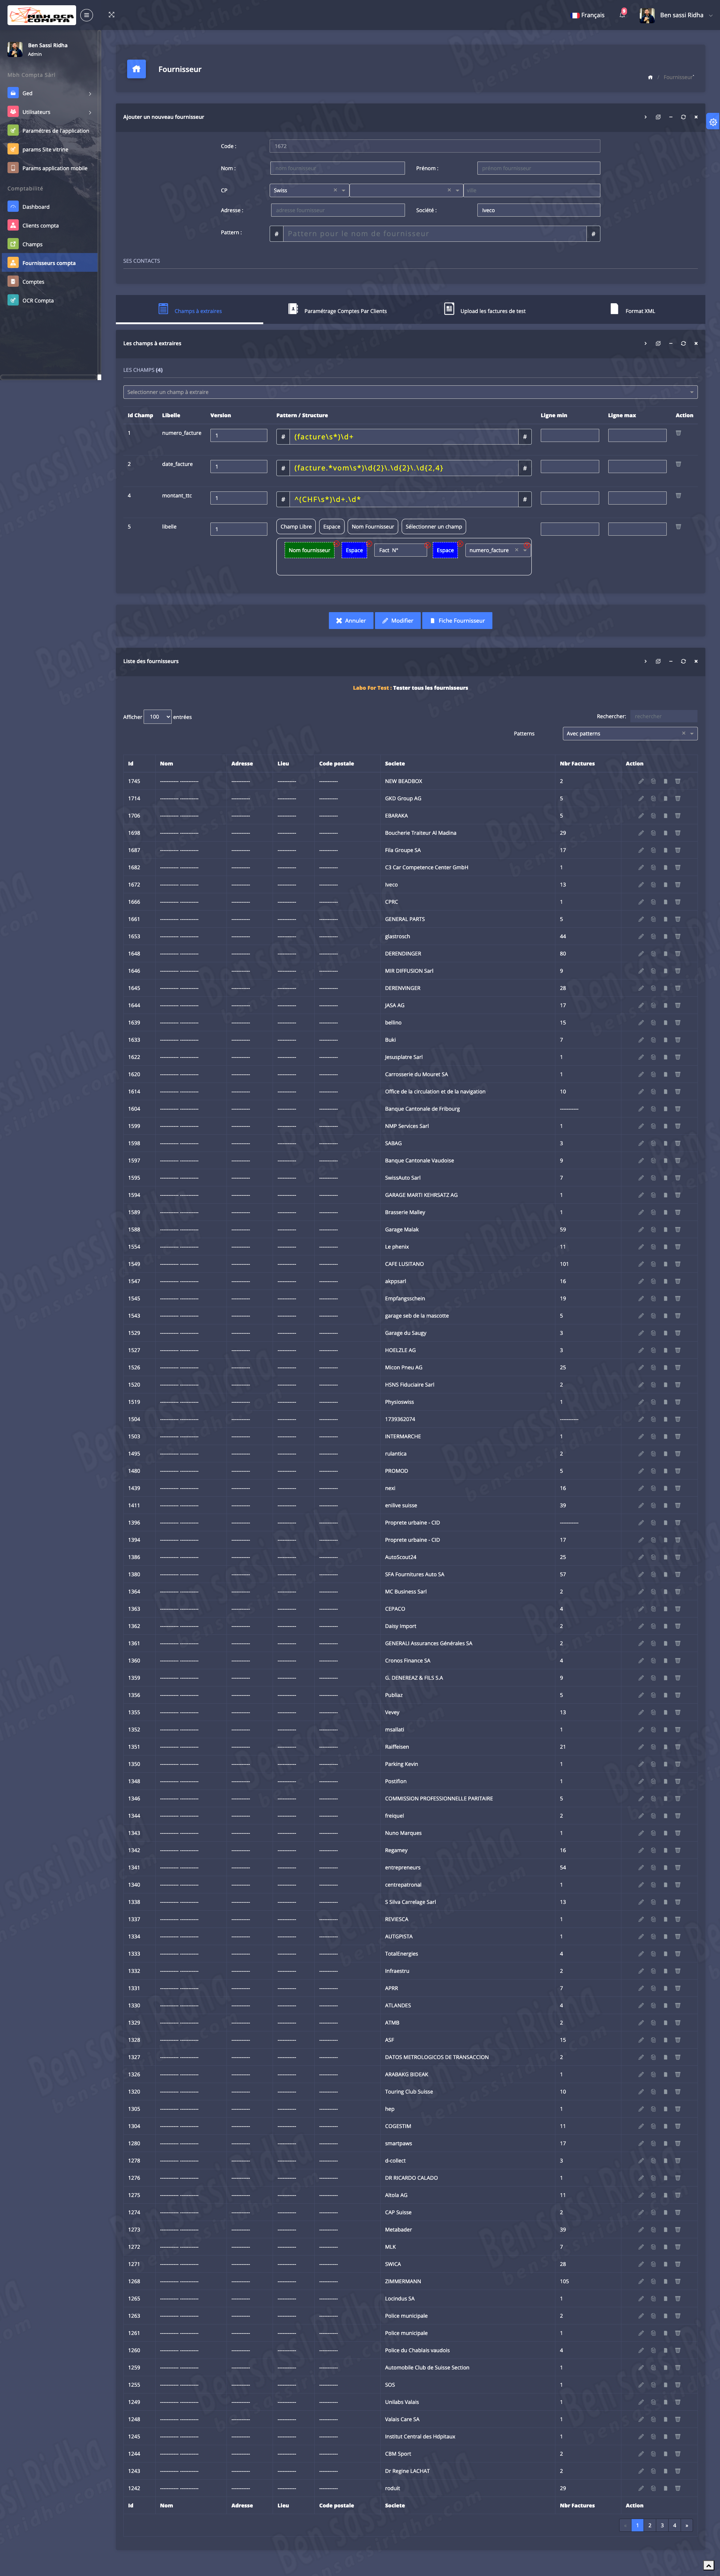
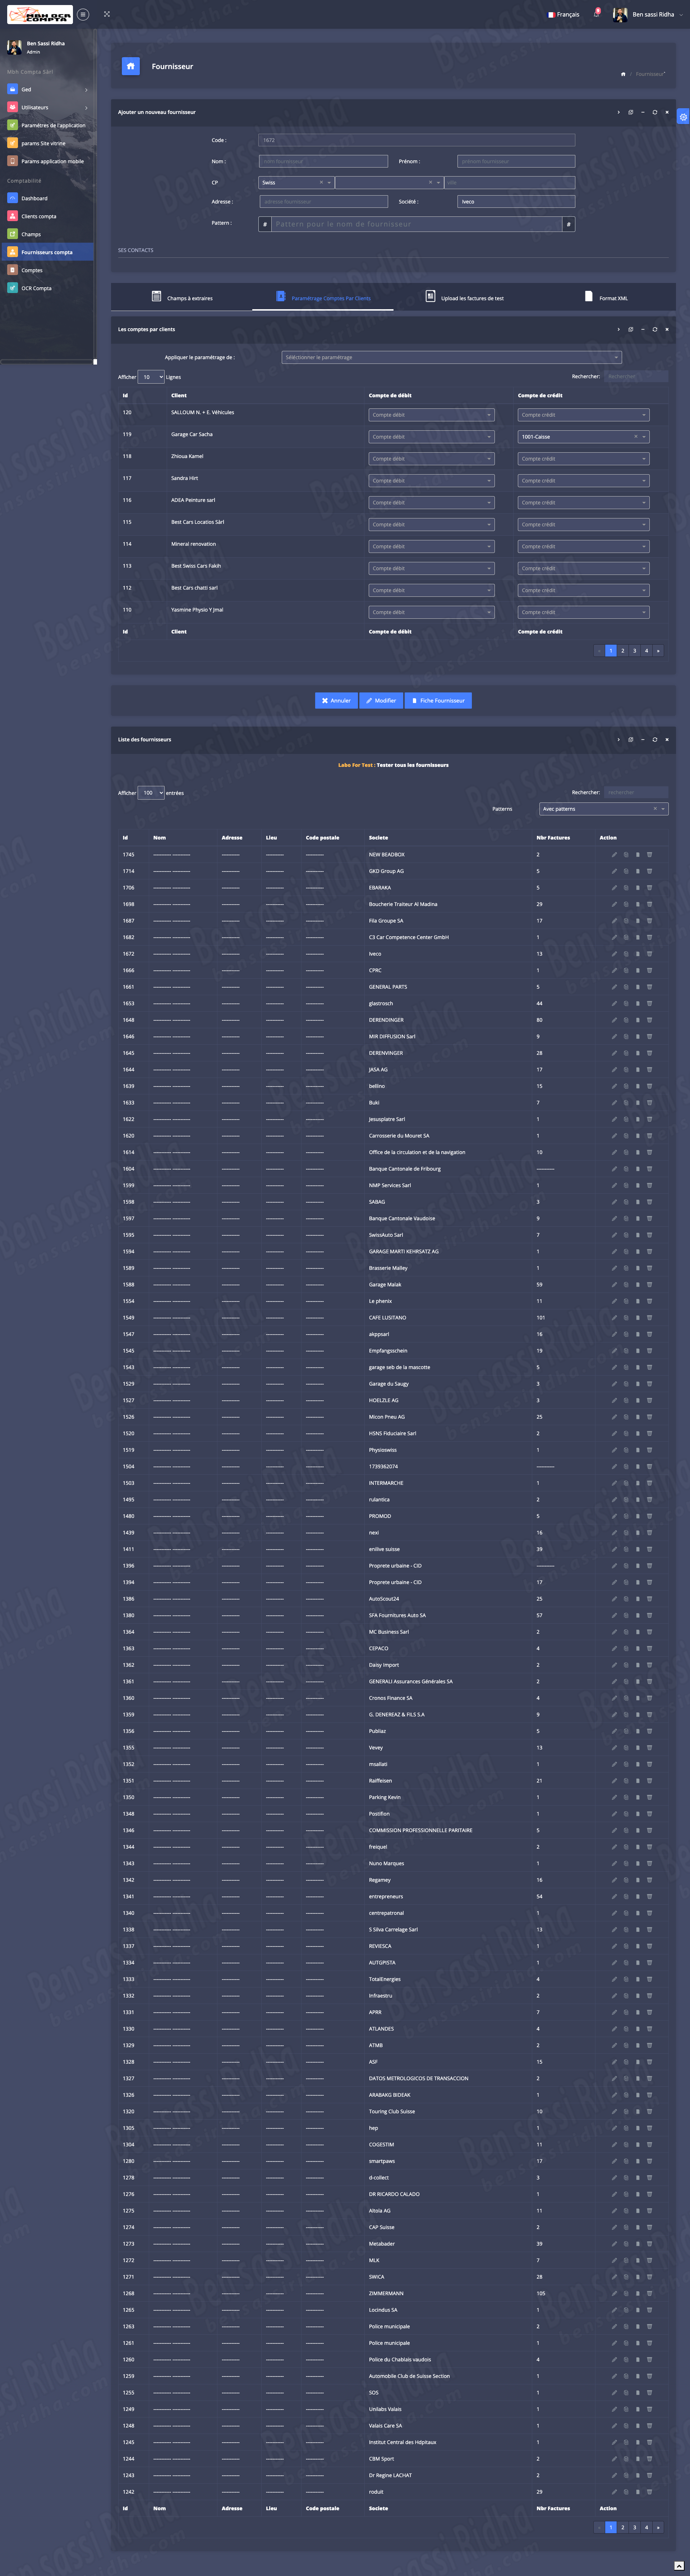
- Manage suppliers
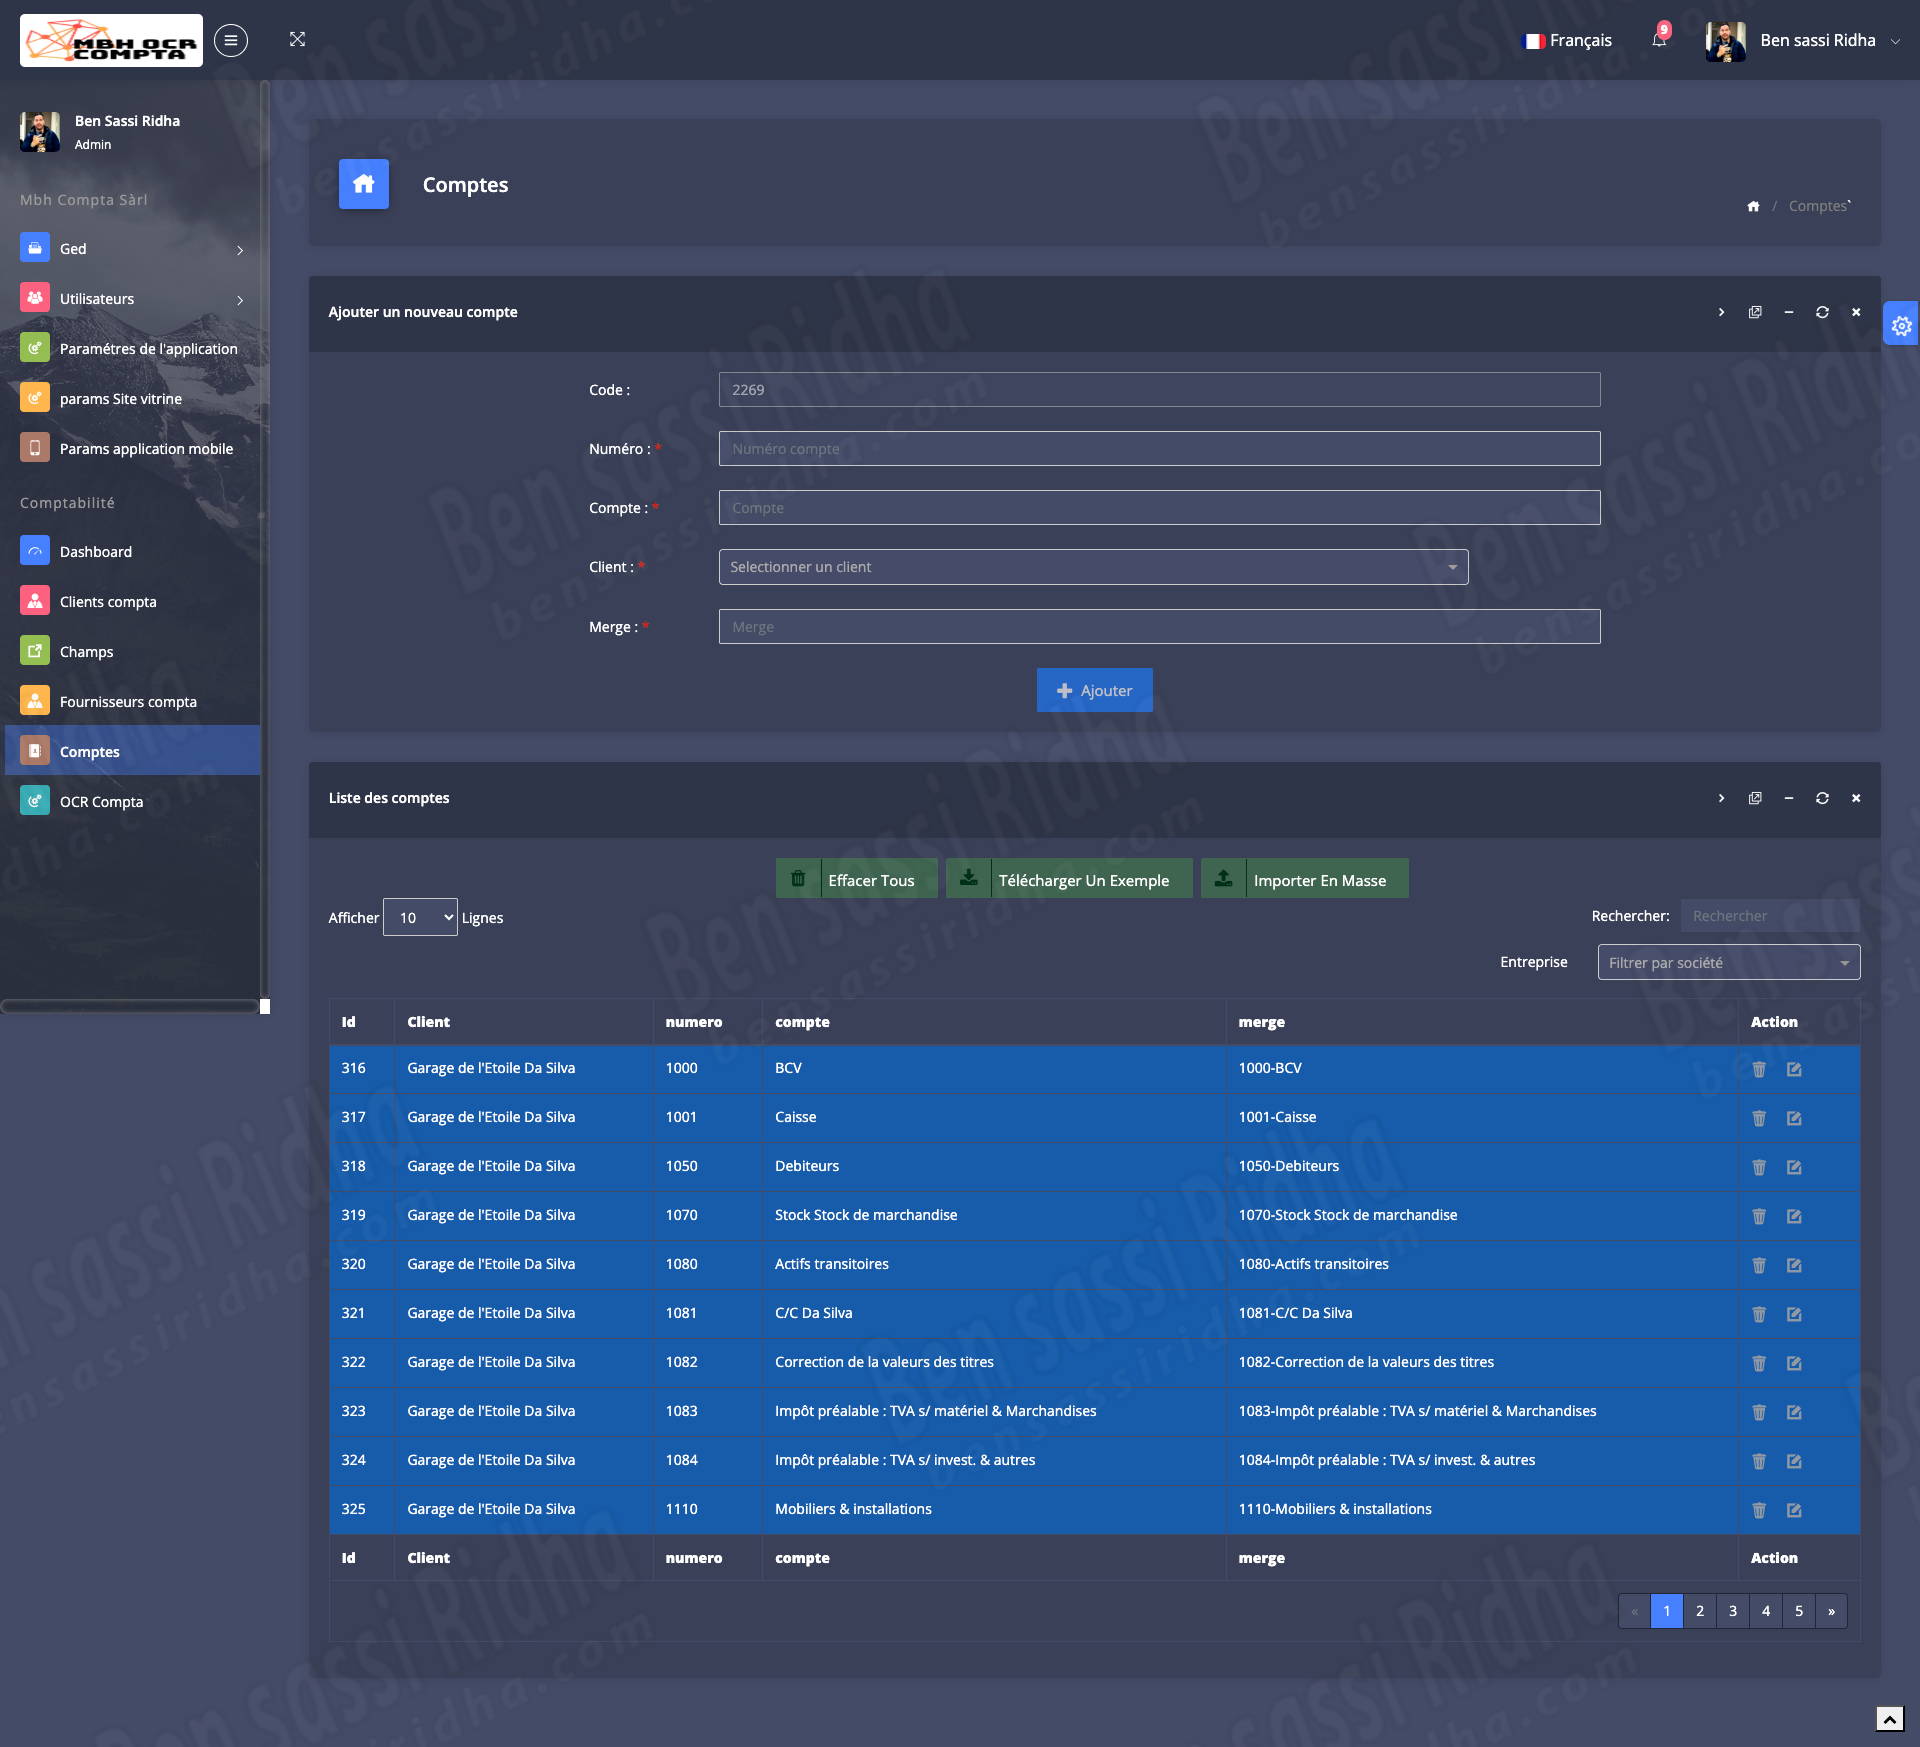
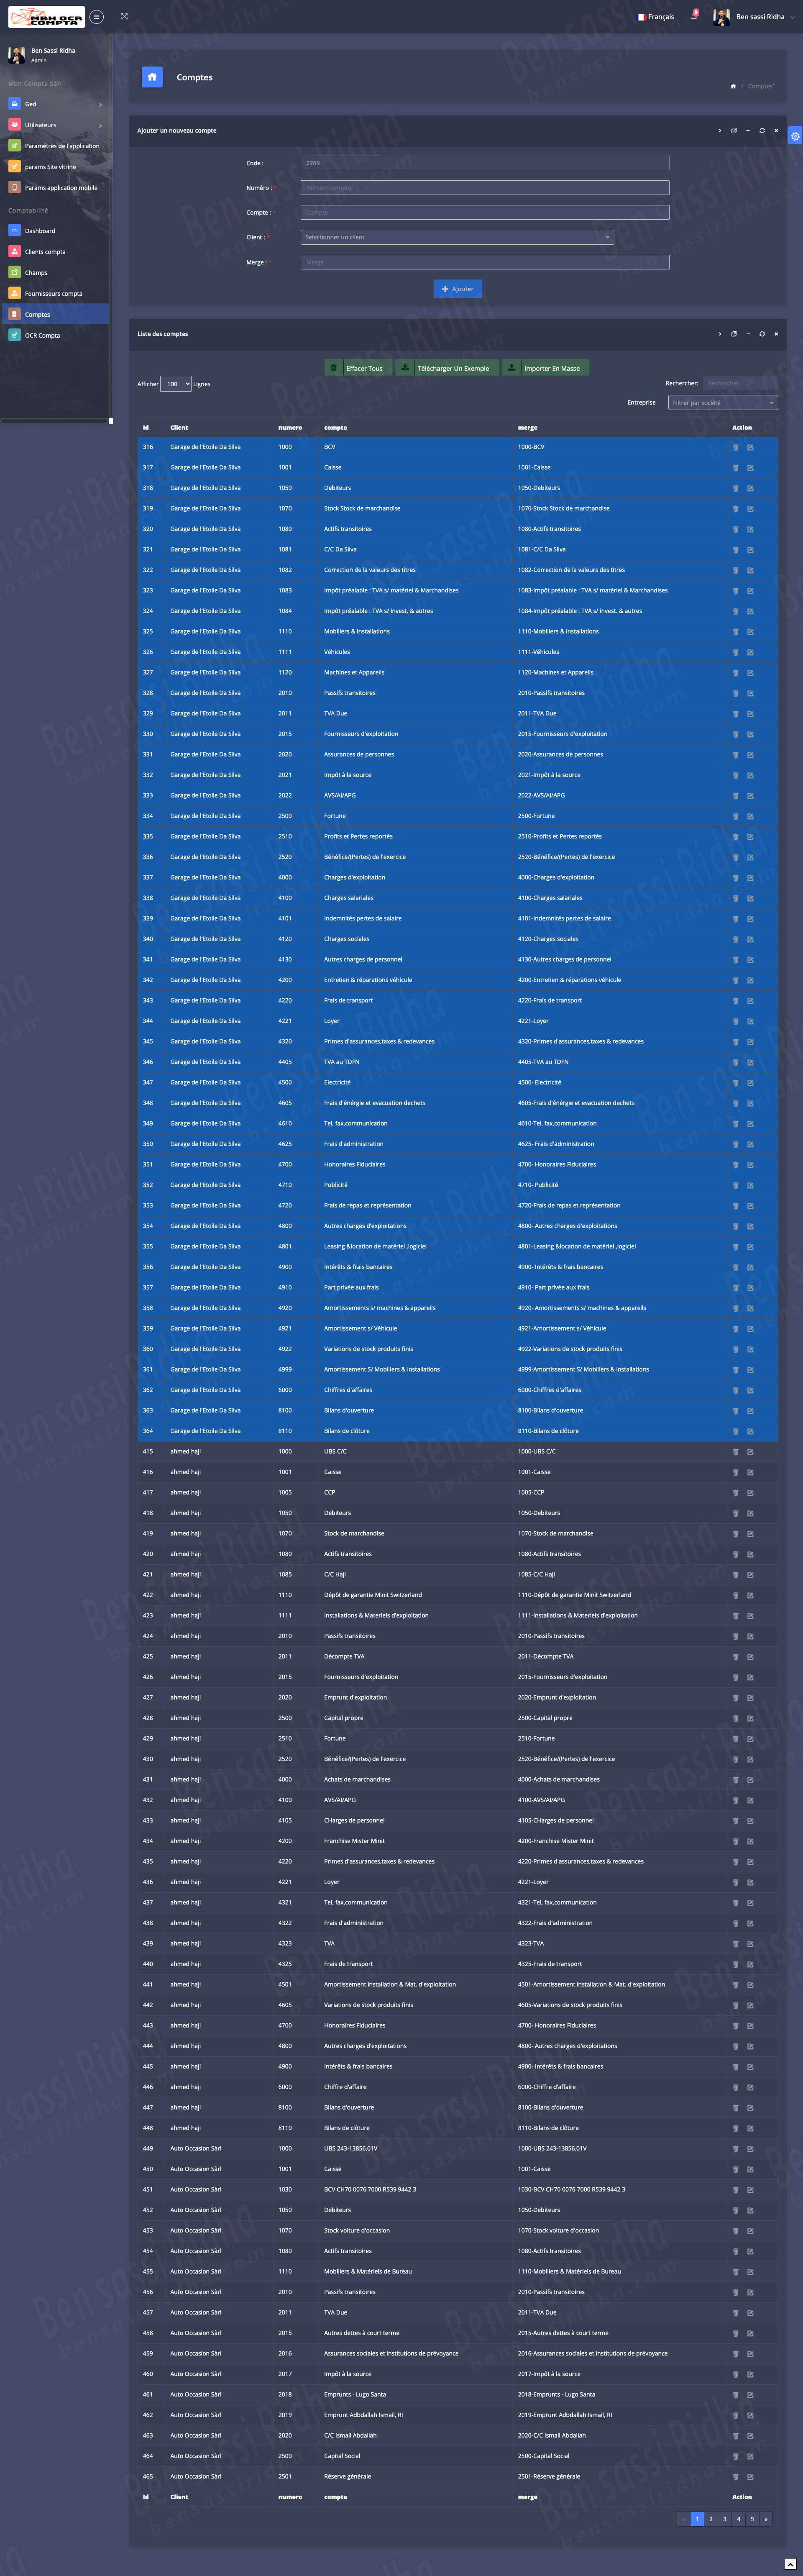
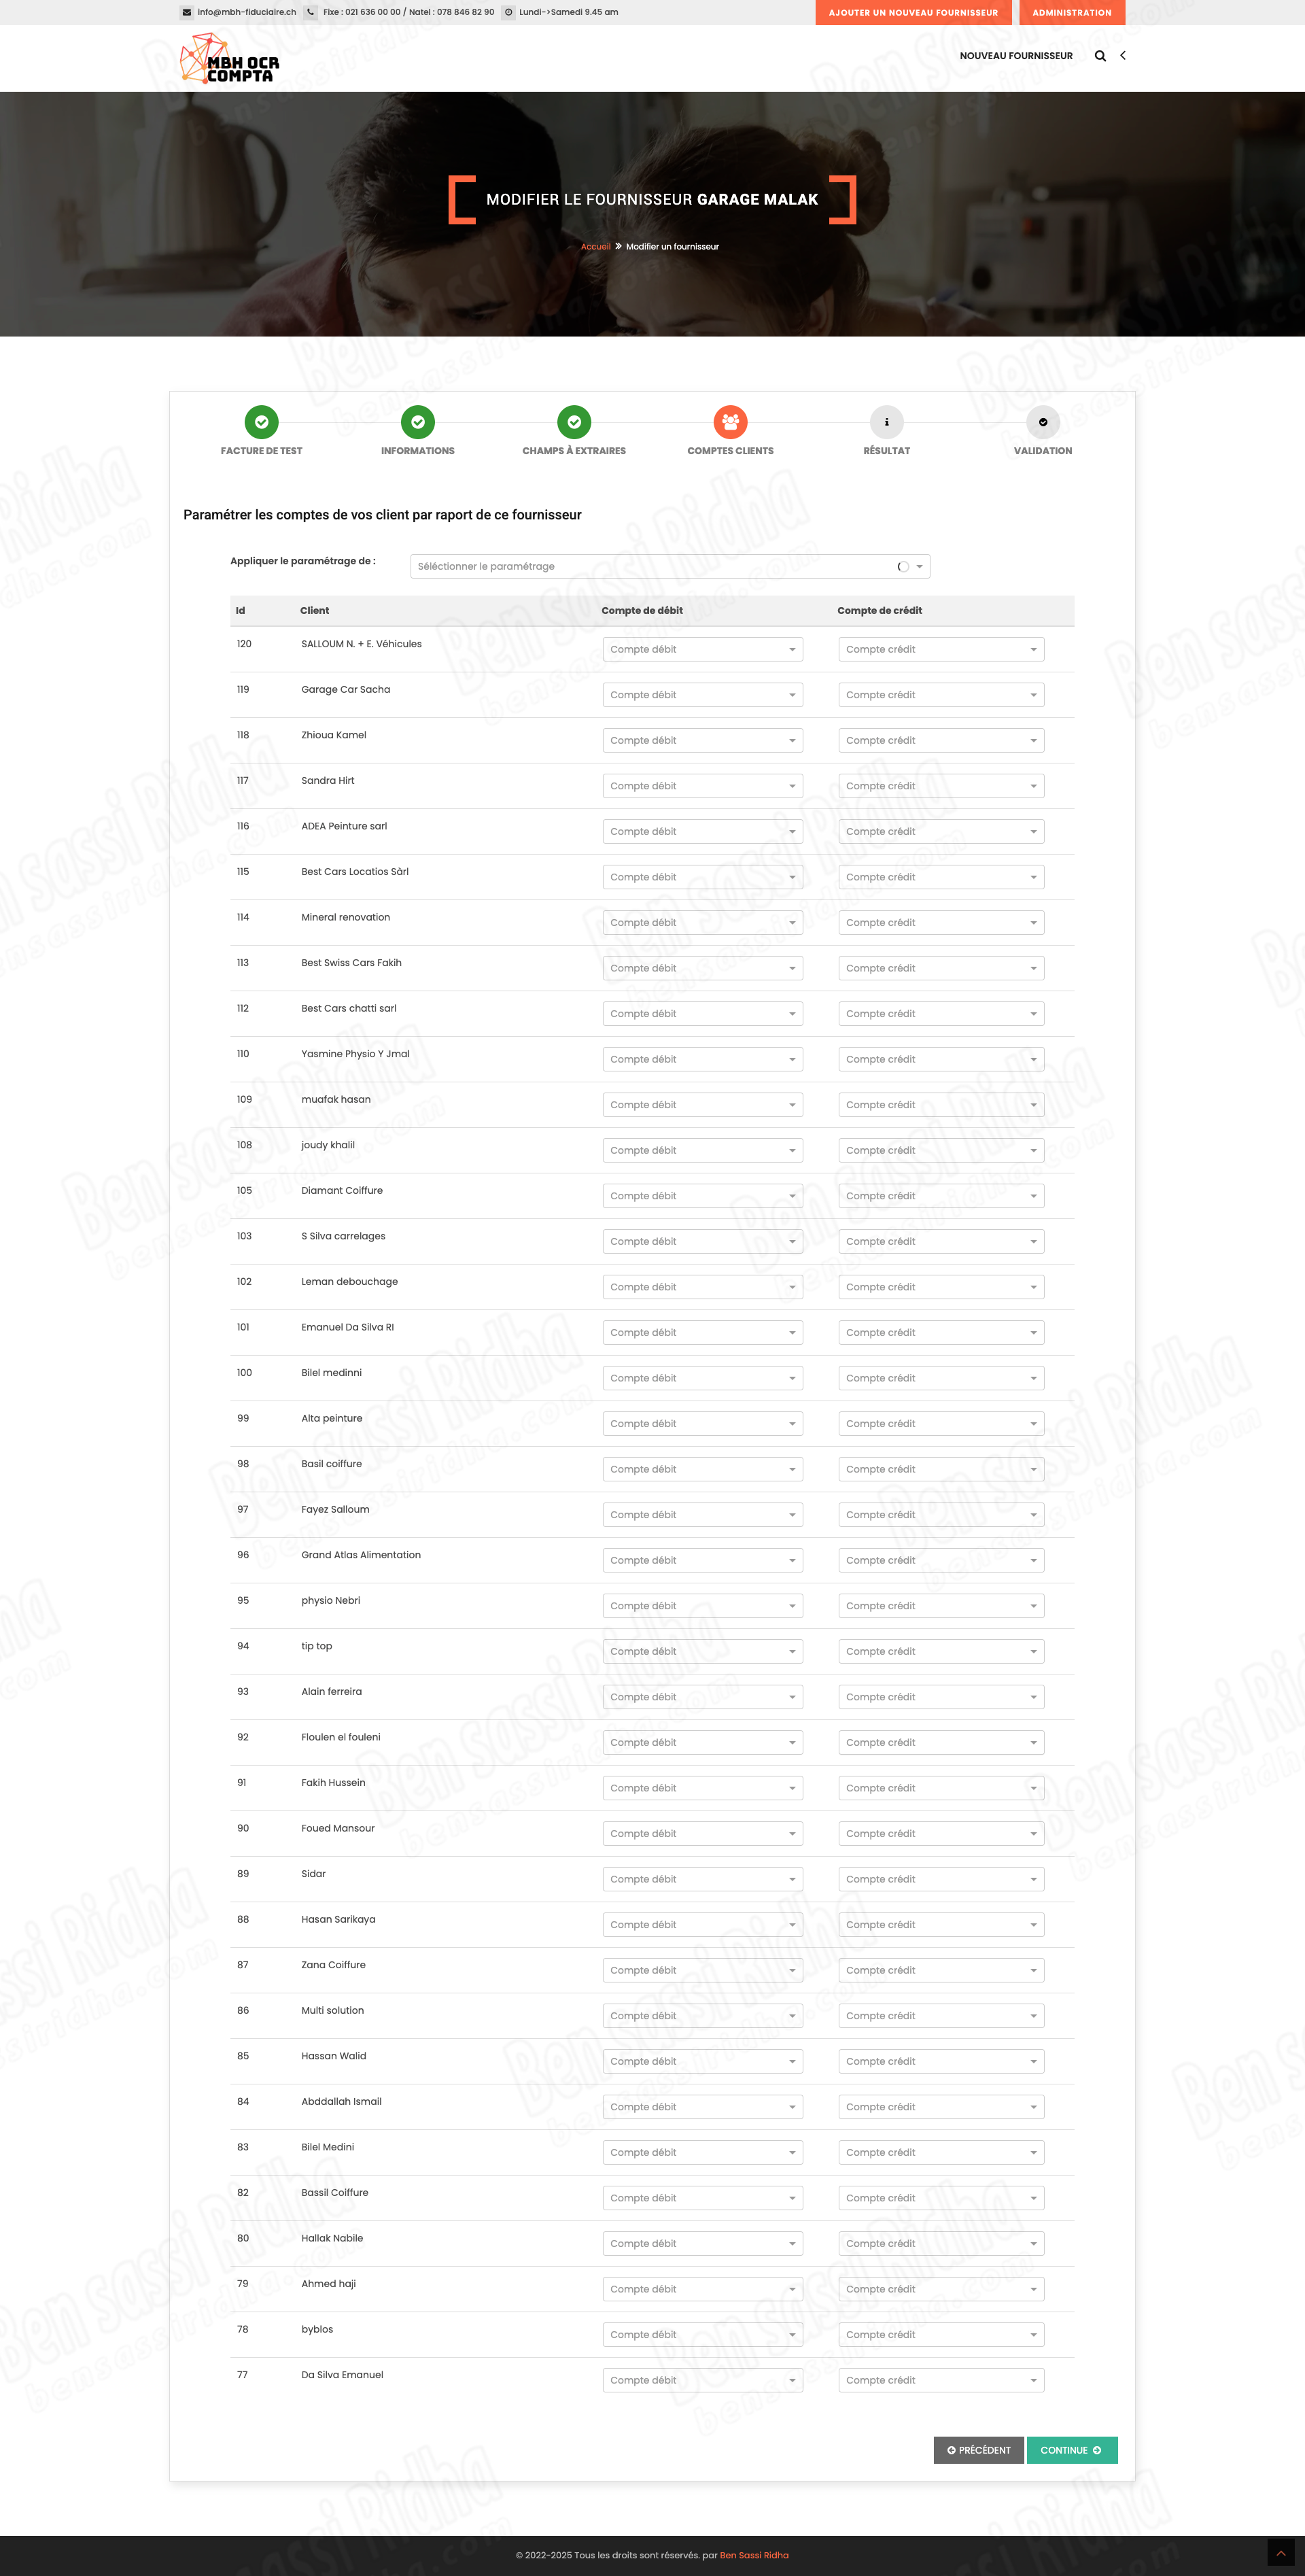
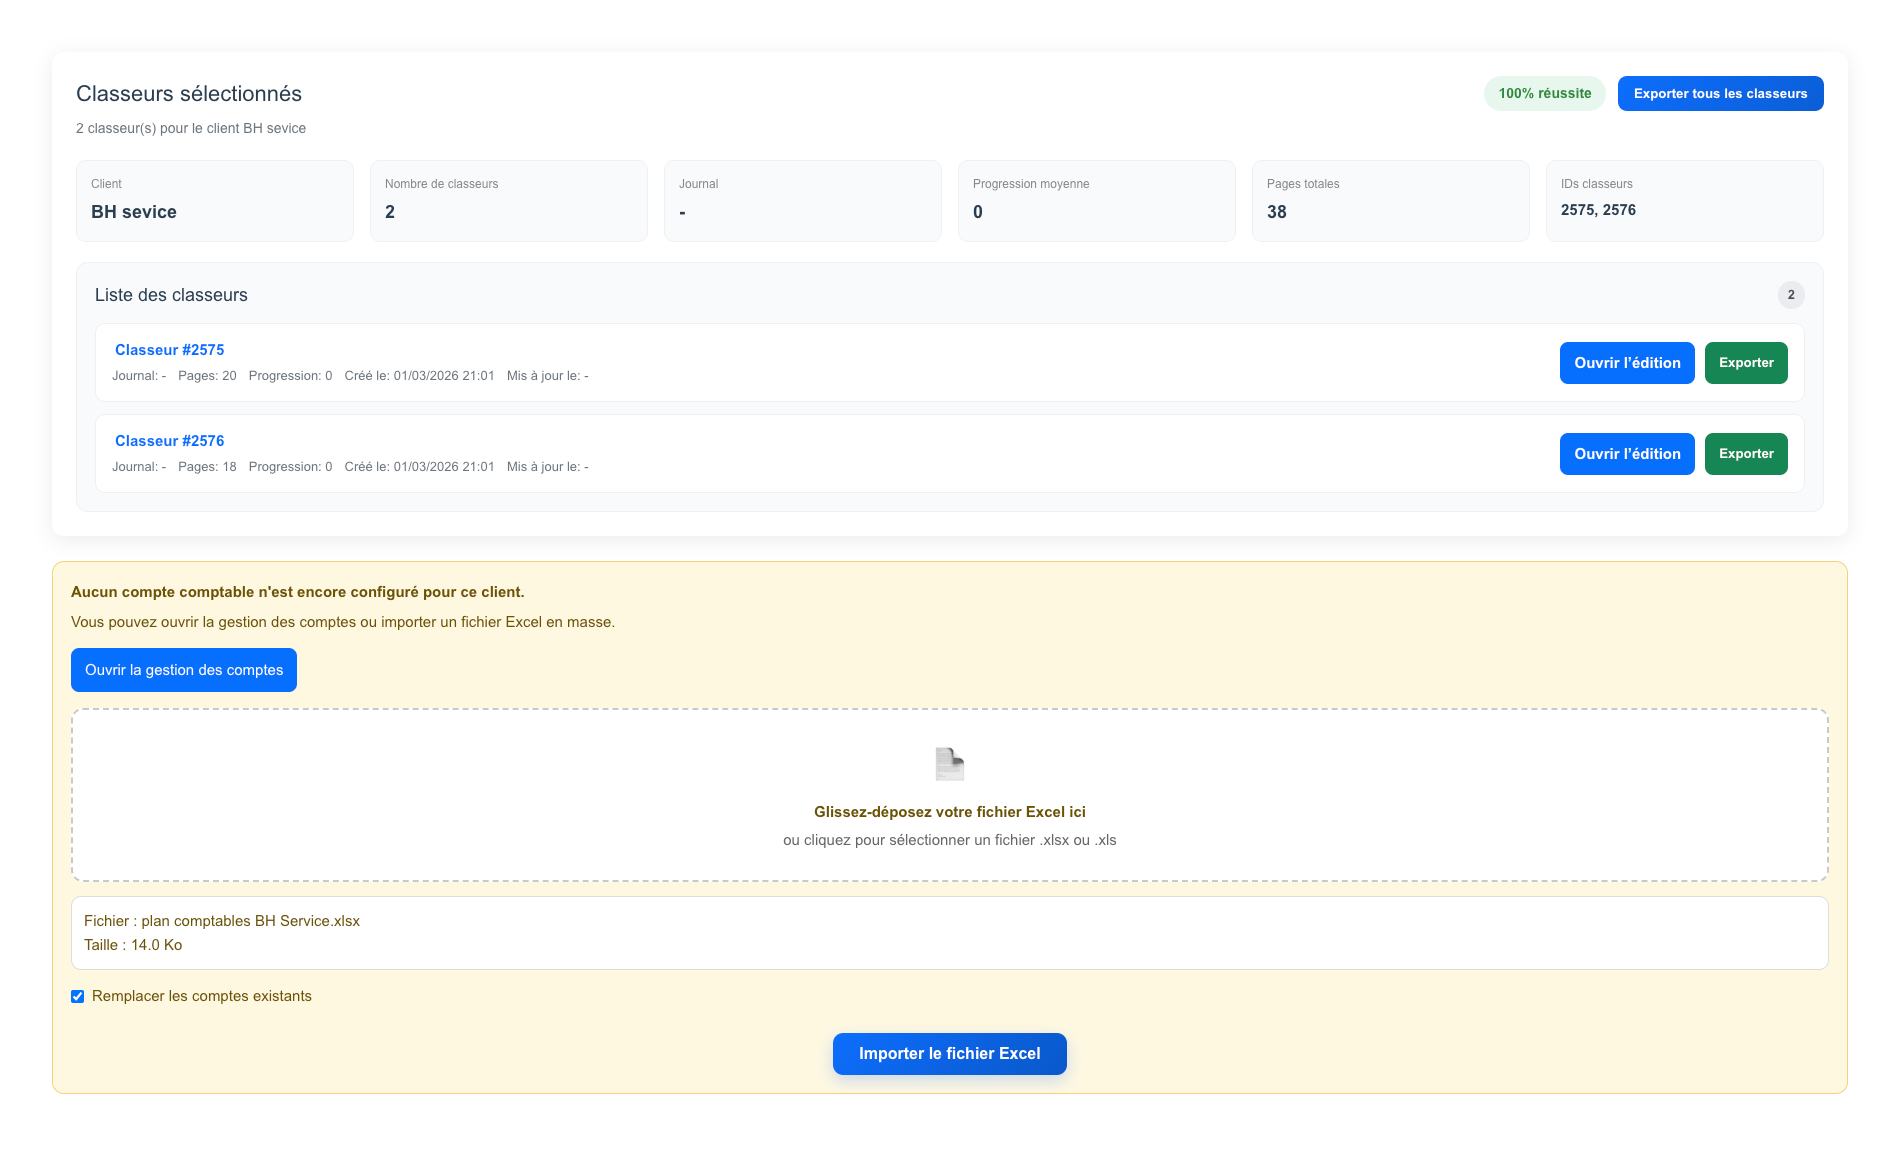
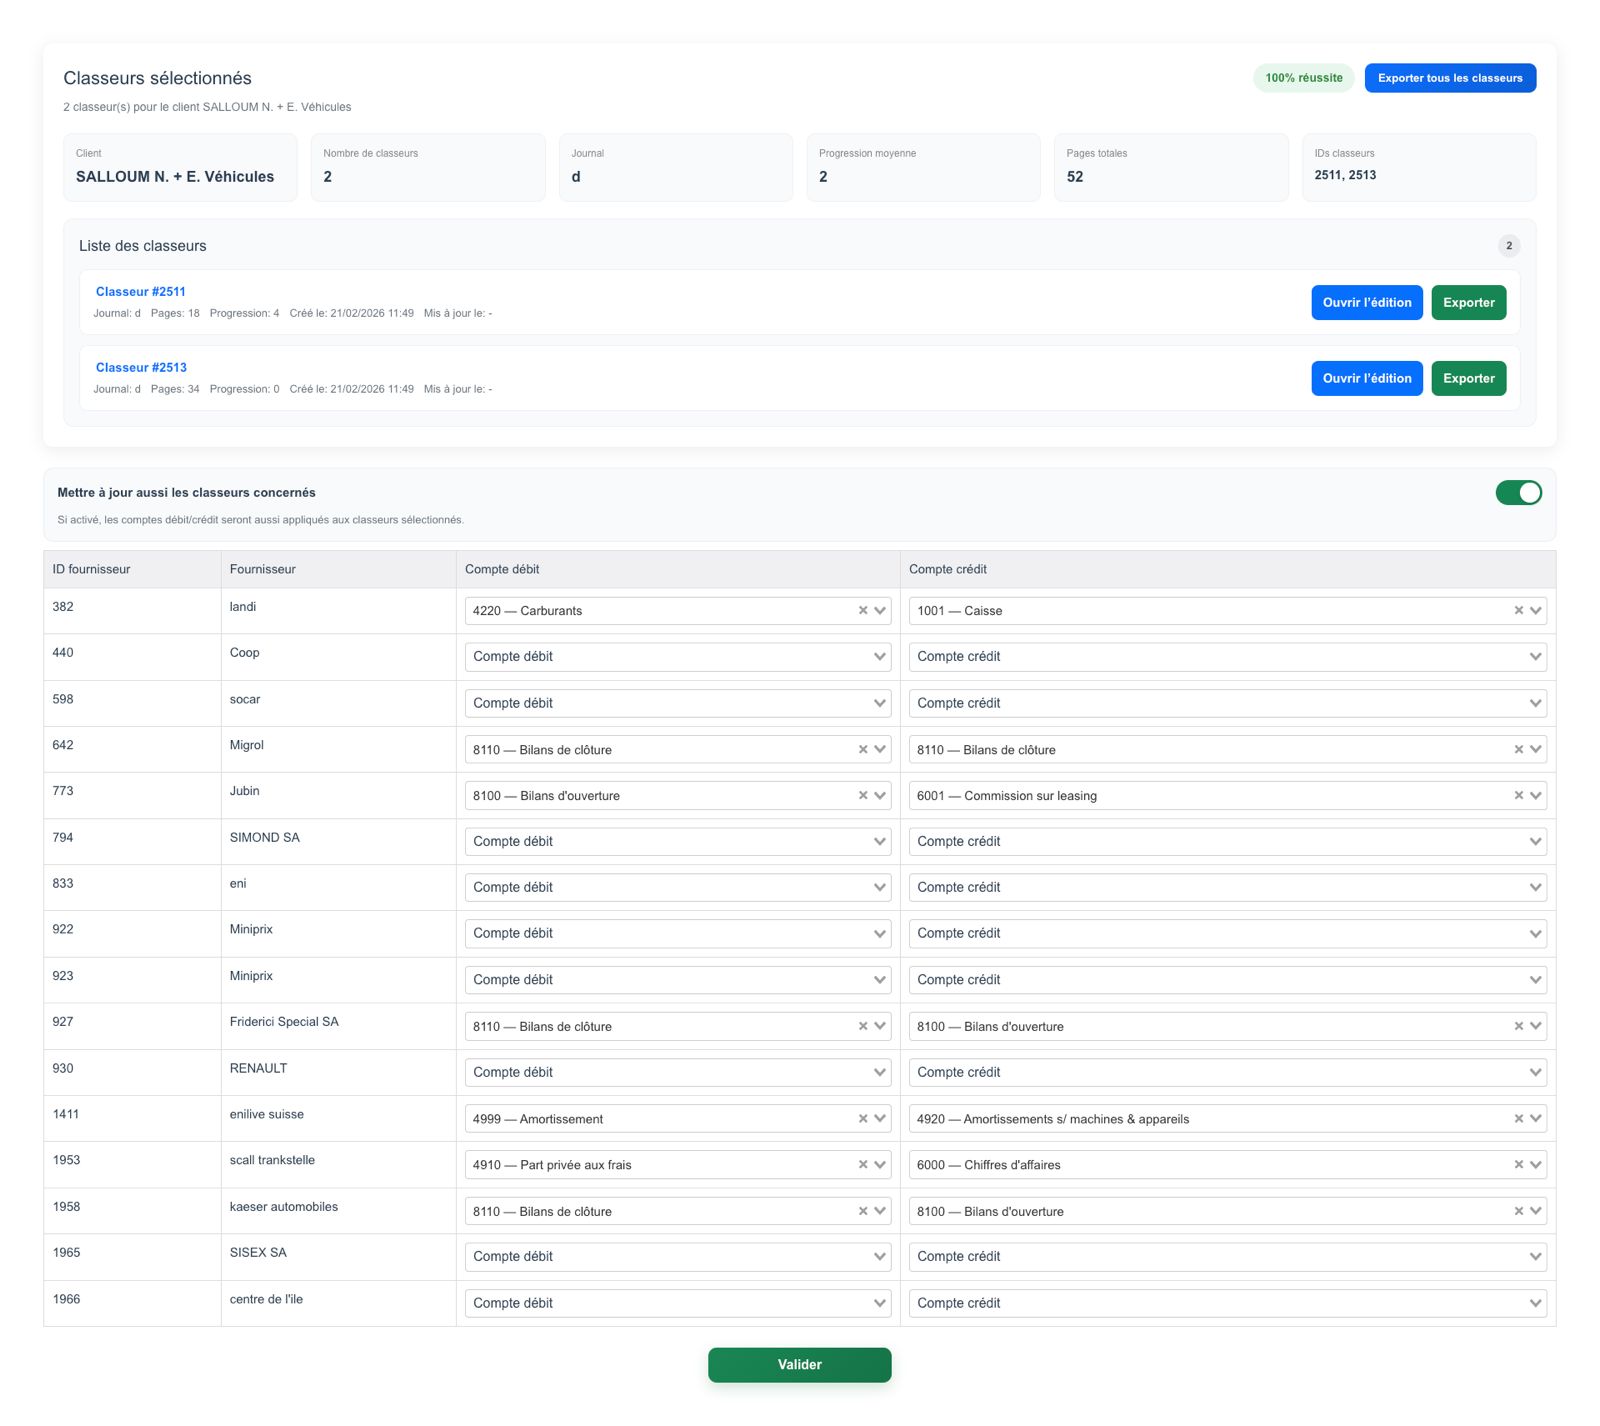
- Manage accounting accounts for each customer
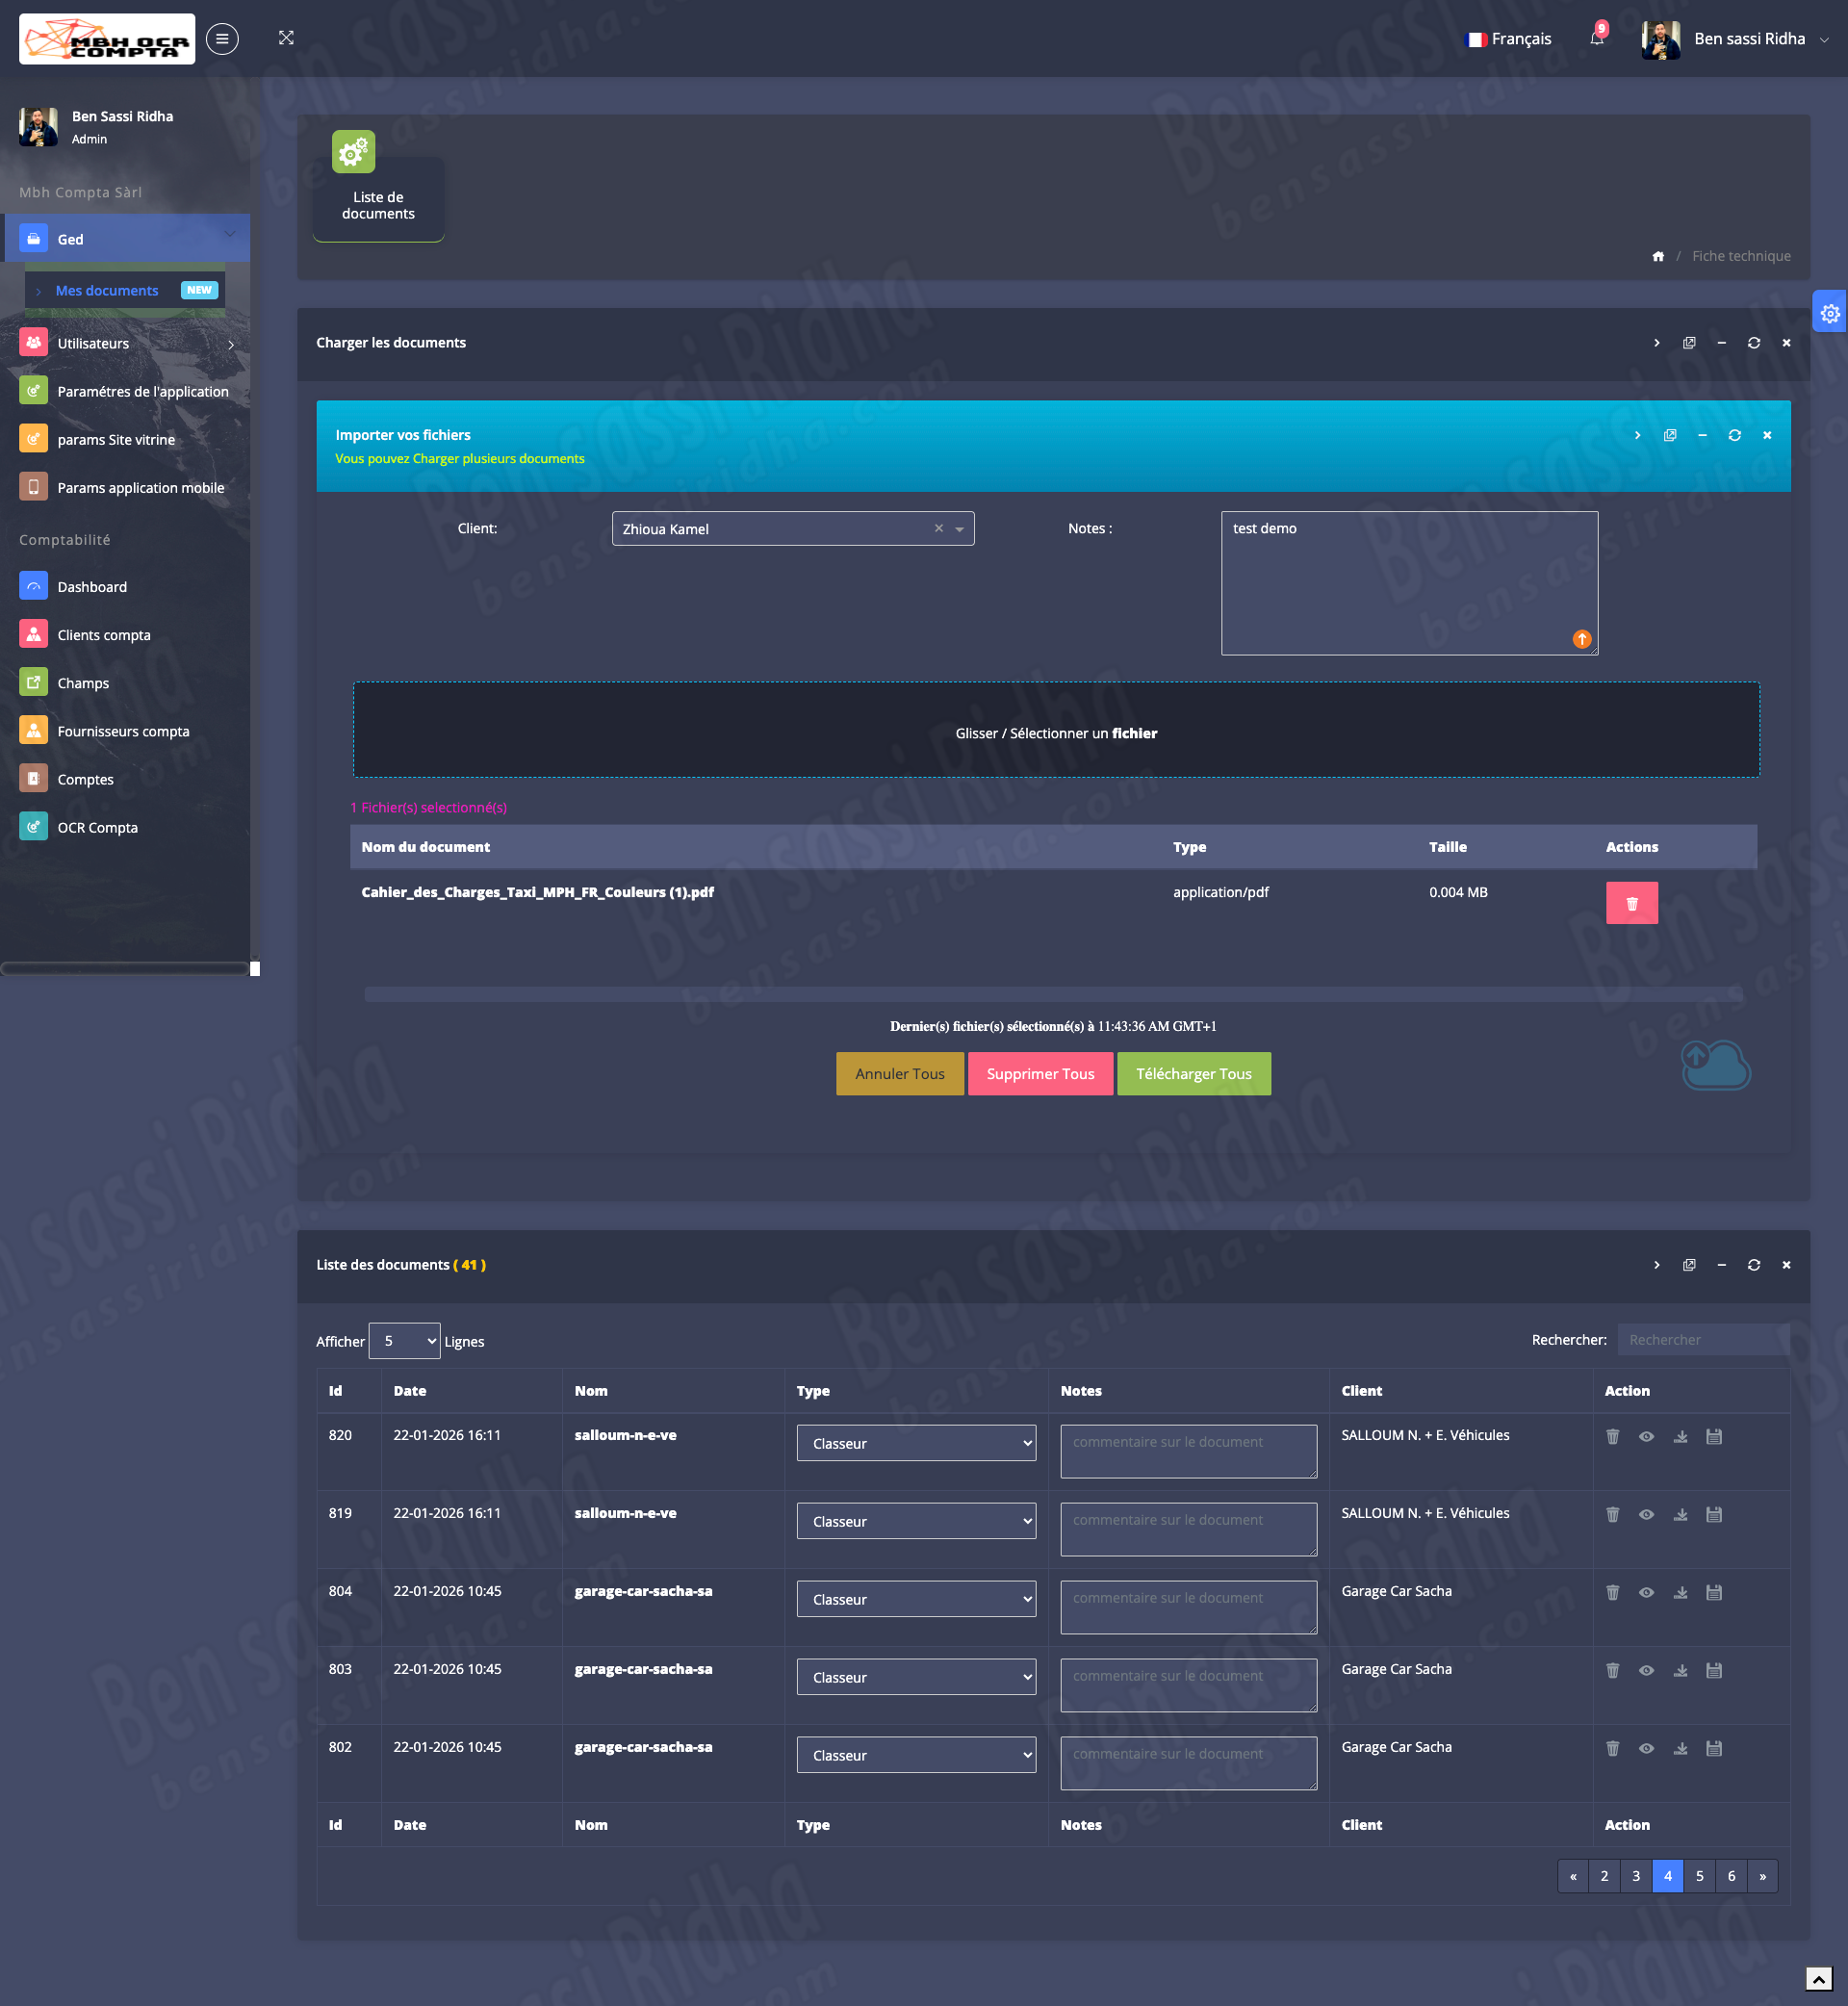
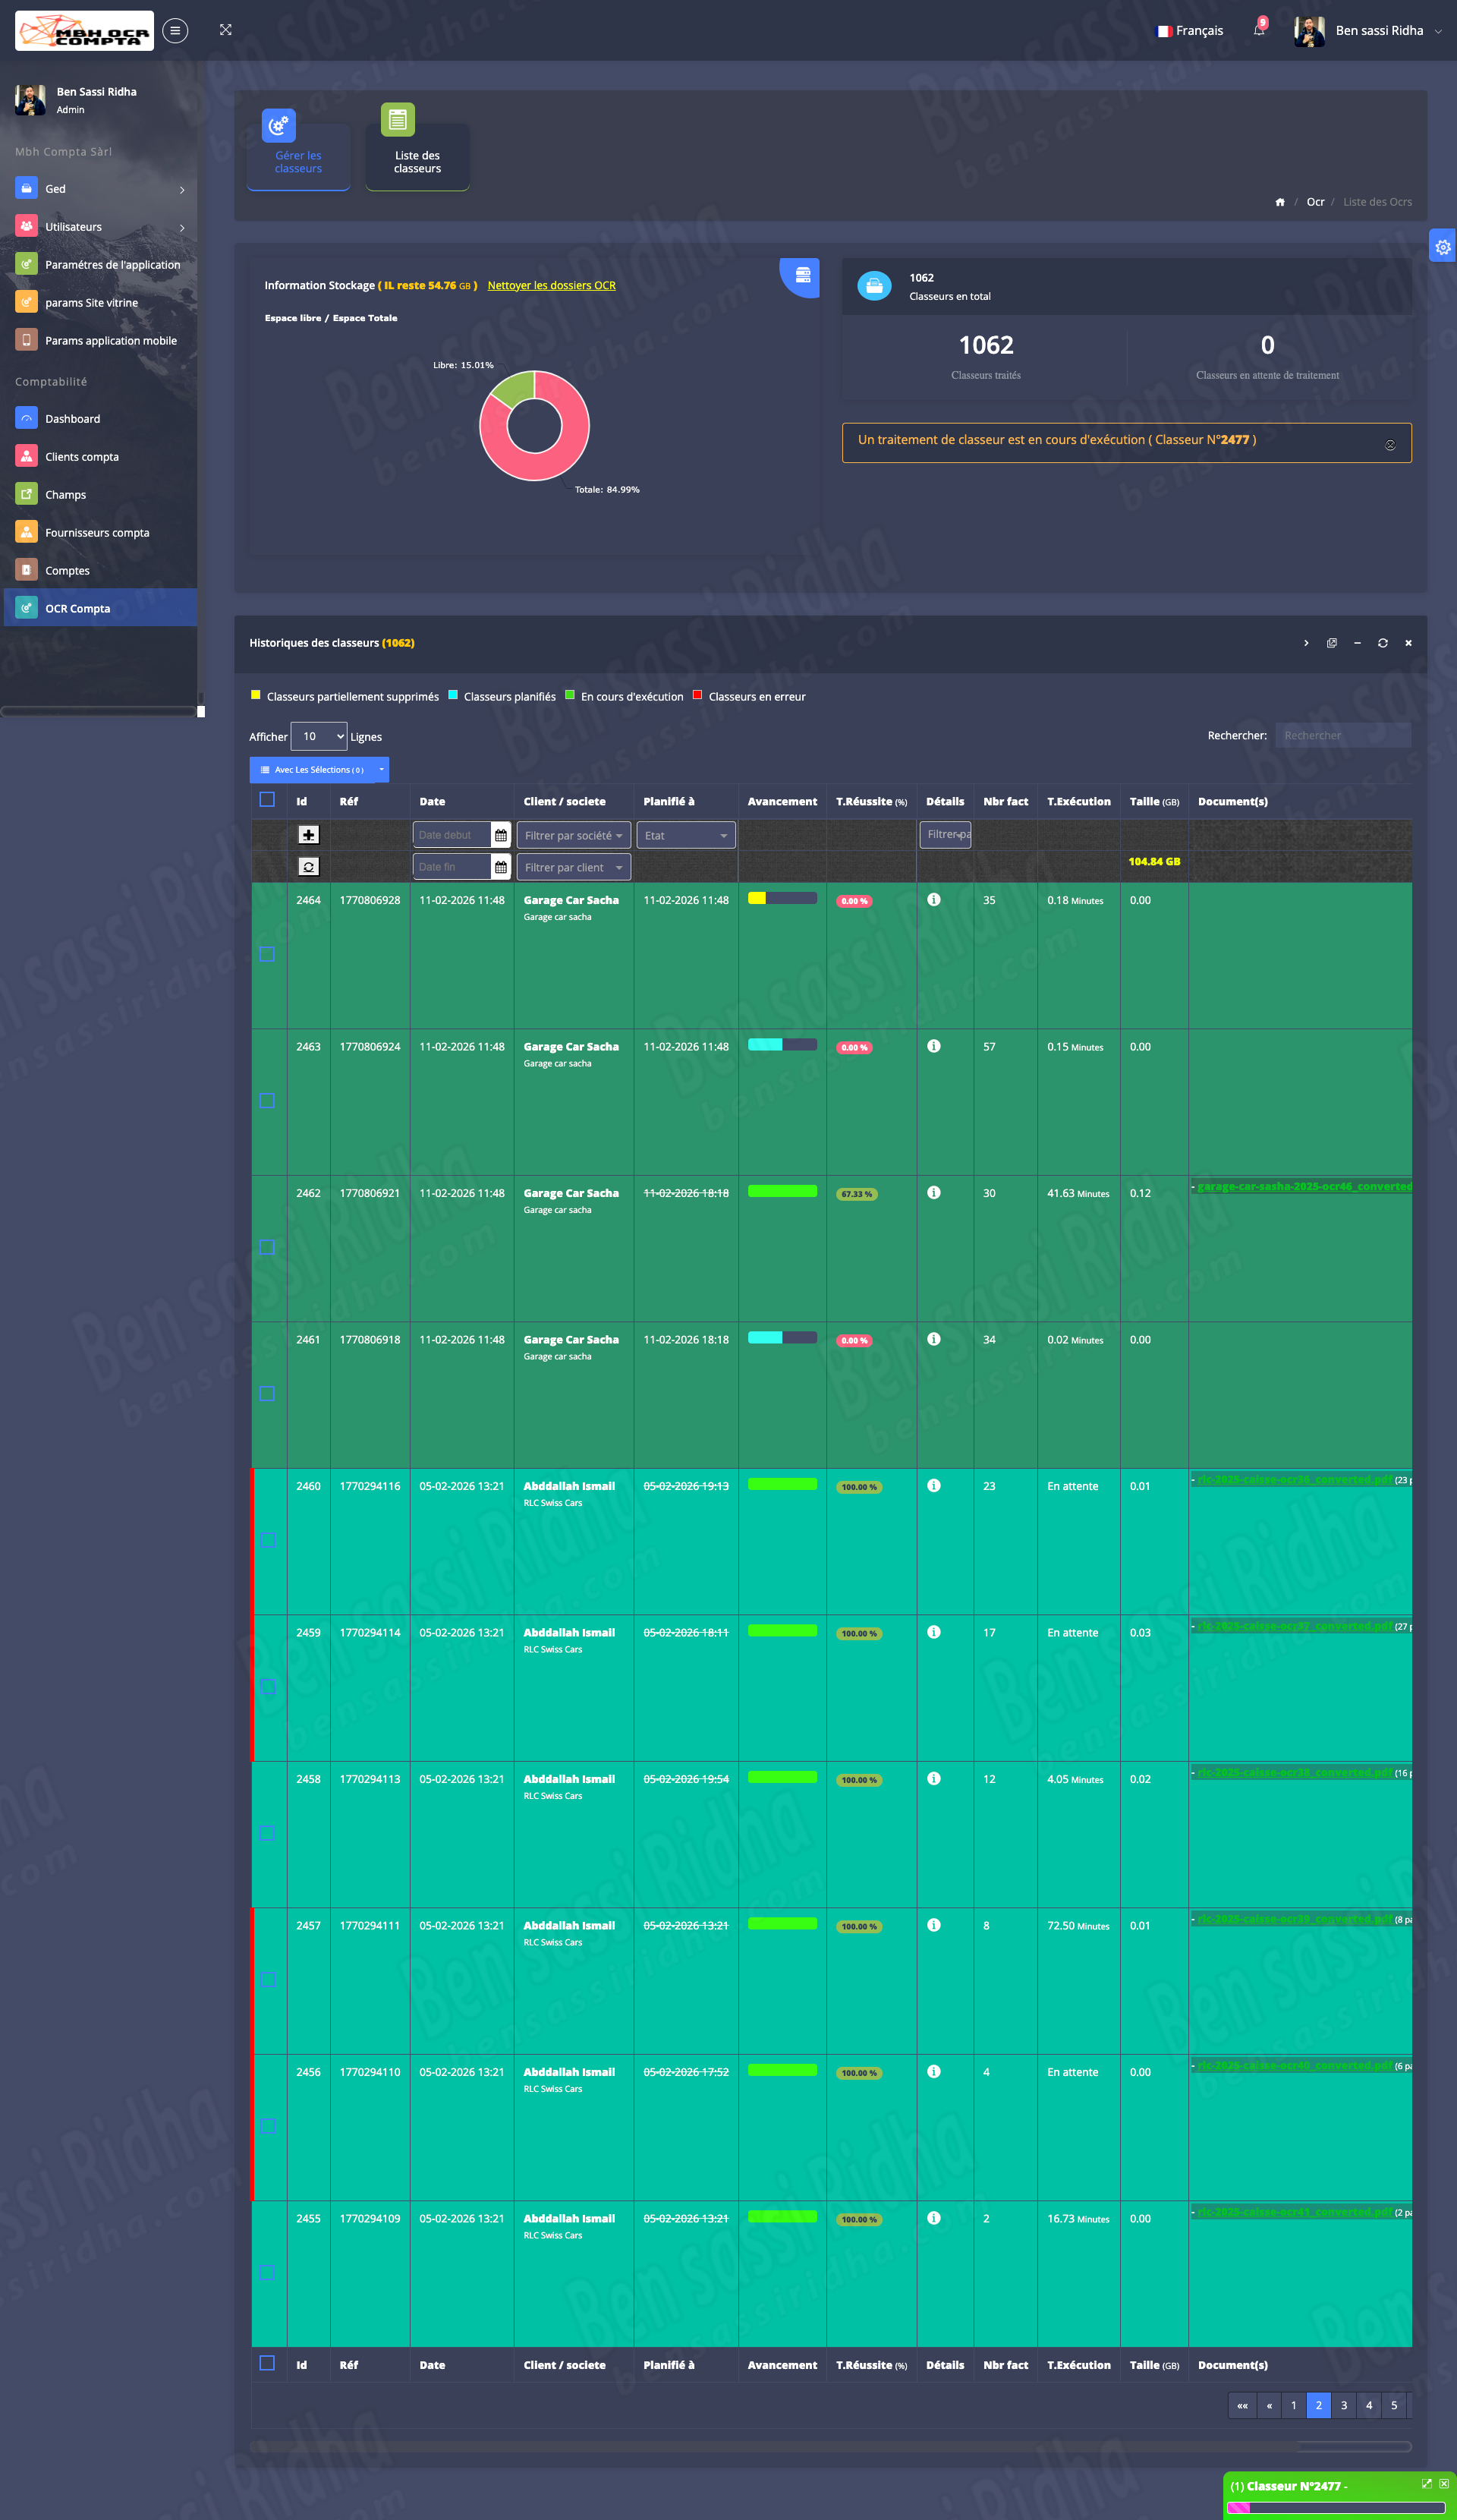
- Consult the list of scanned invoices and their fields which have been extracted
- Export the result of an OCR to an Excel file
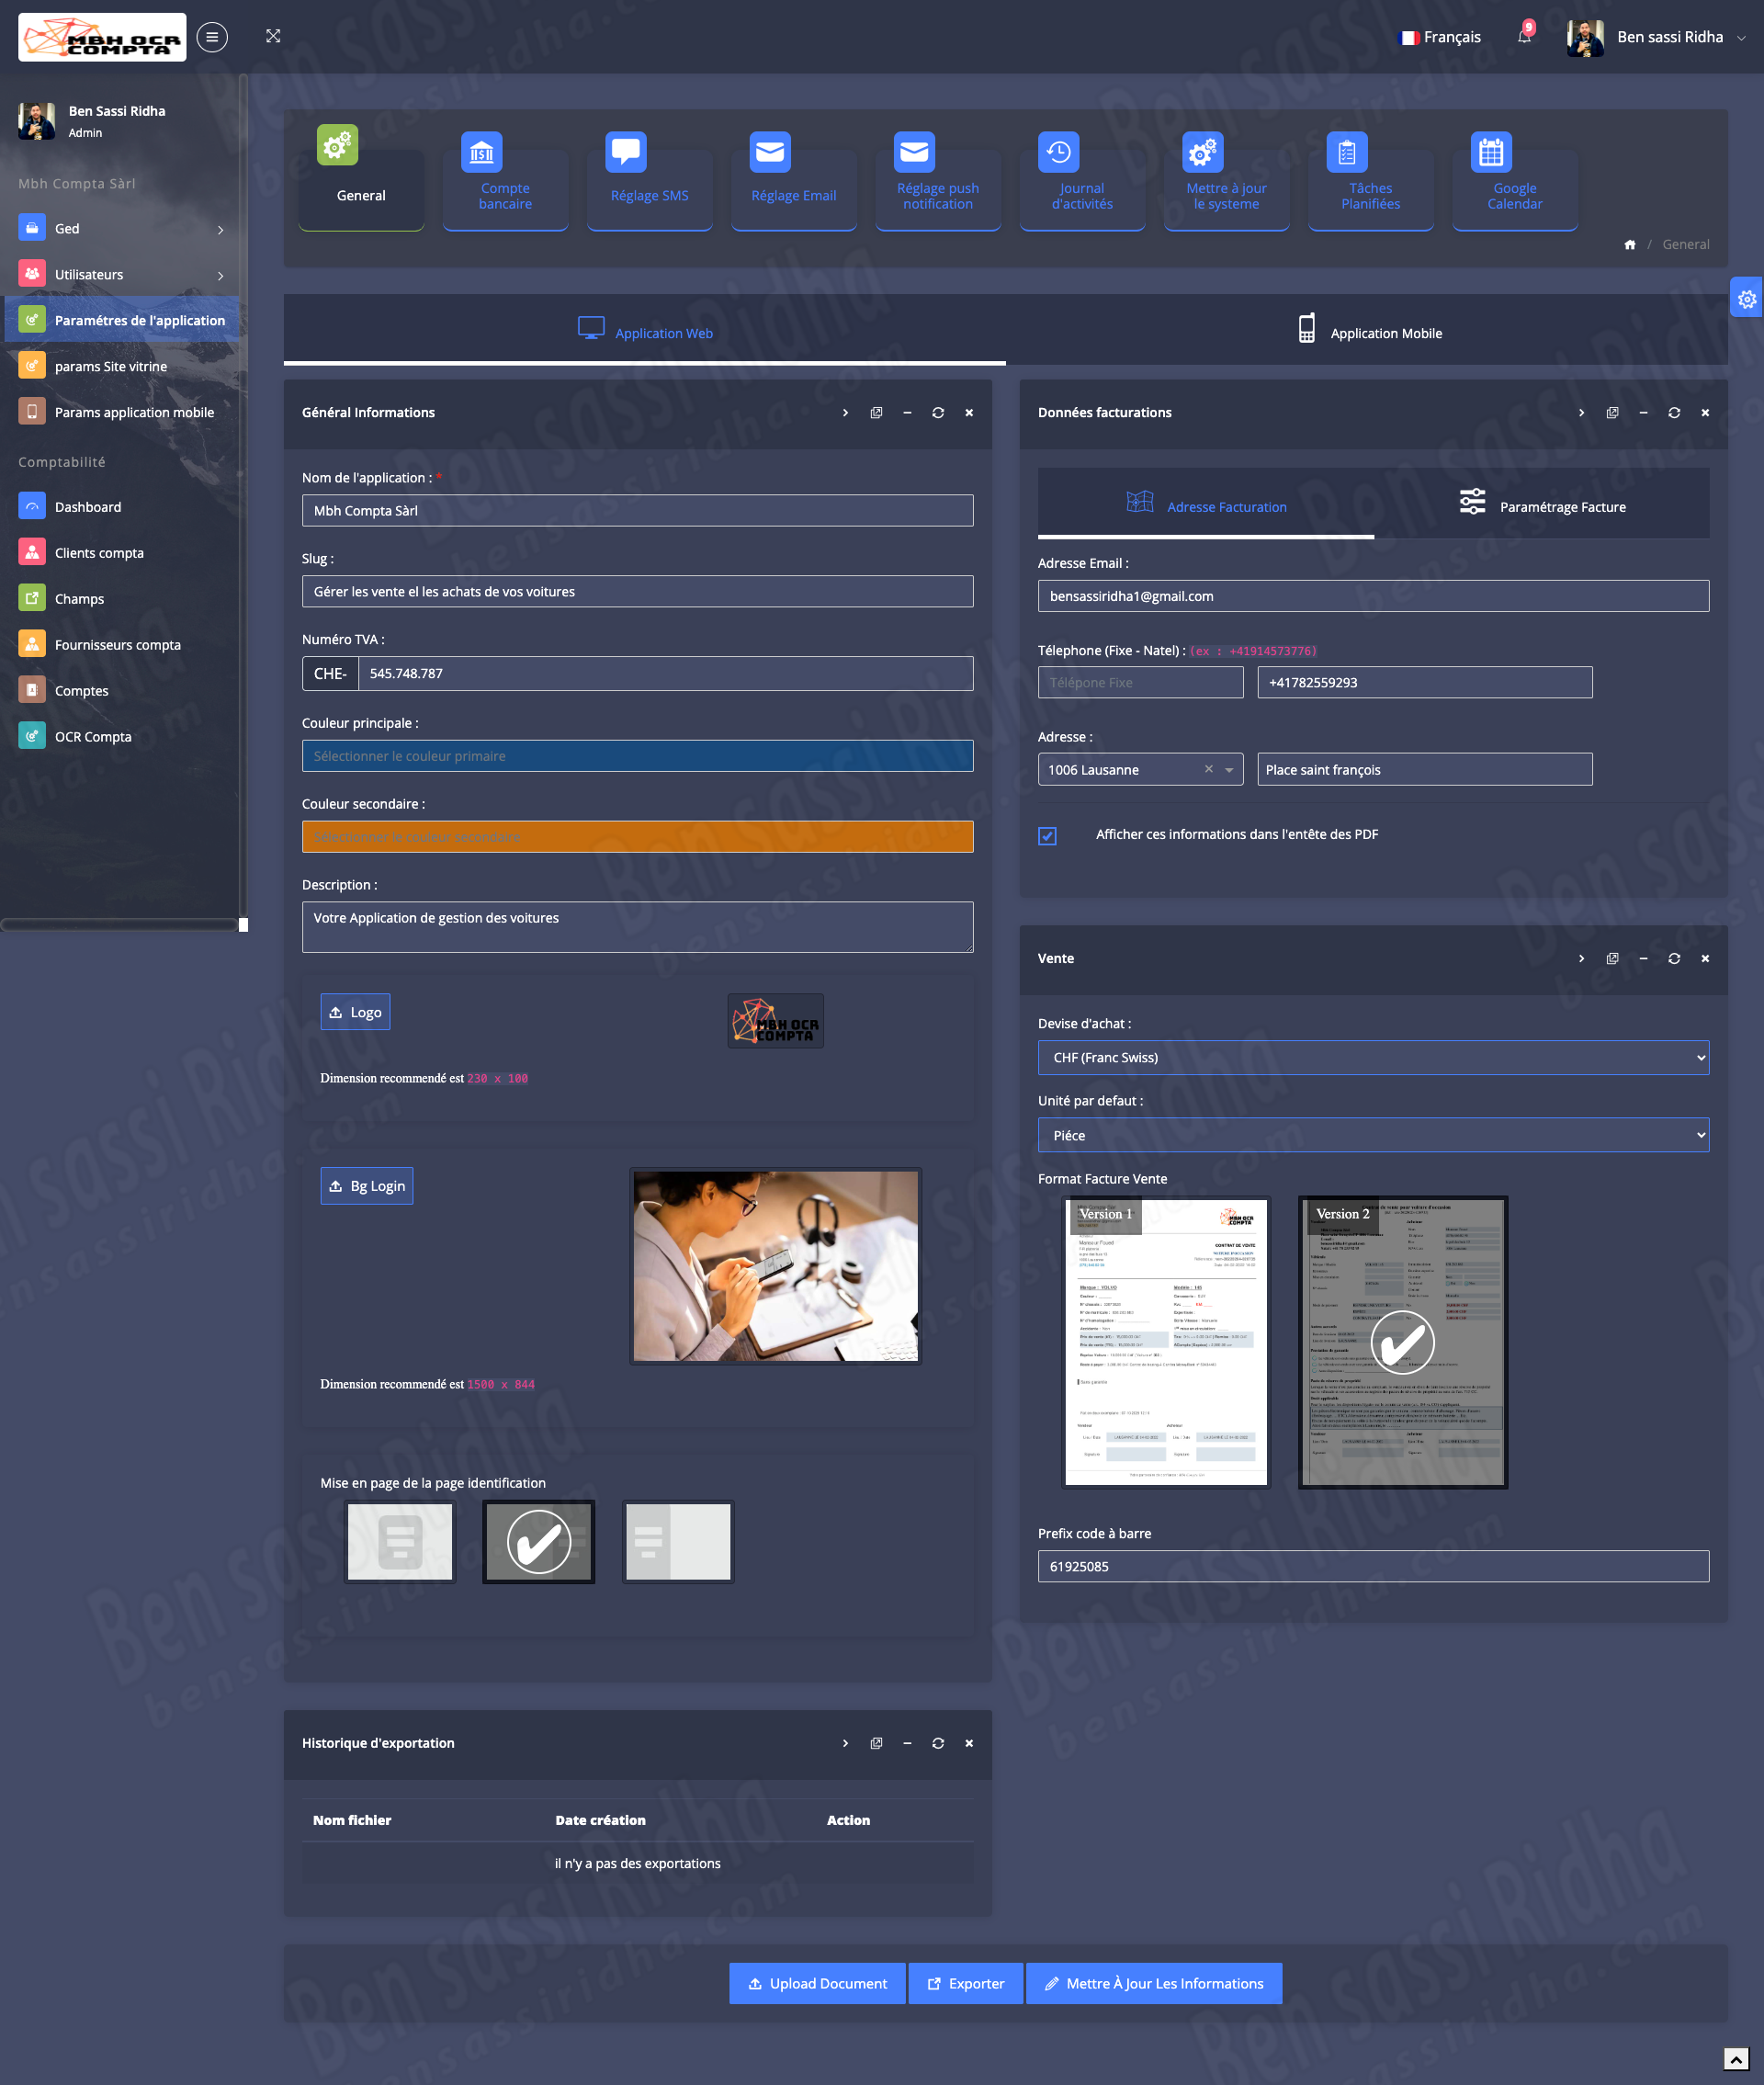
- Manage application settings (roles, permissions, users, activity history)
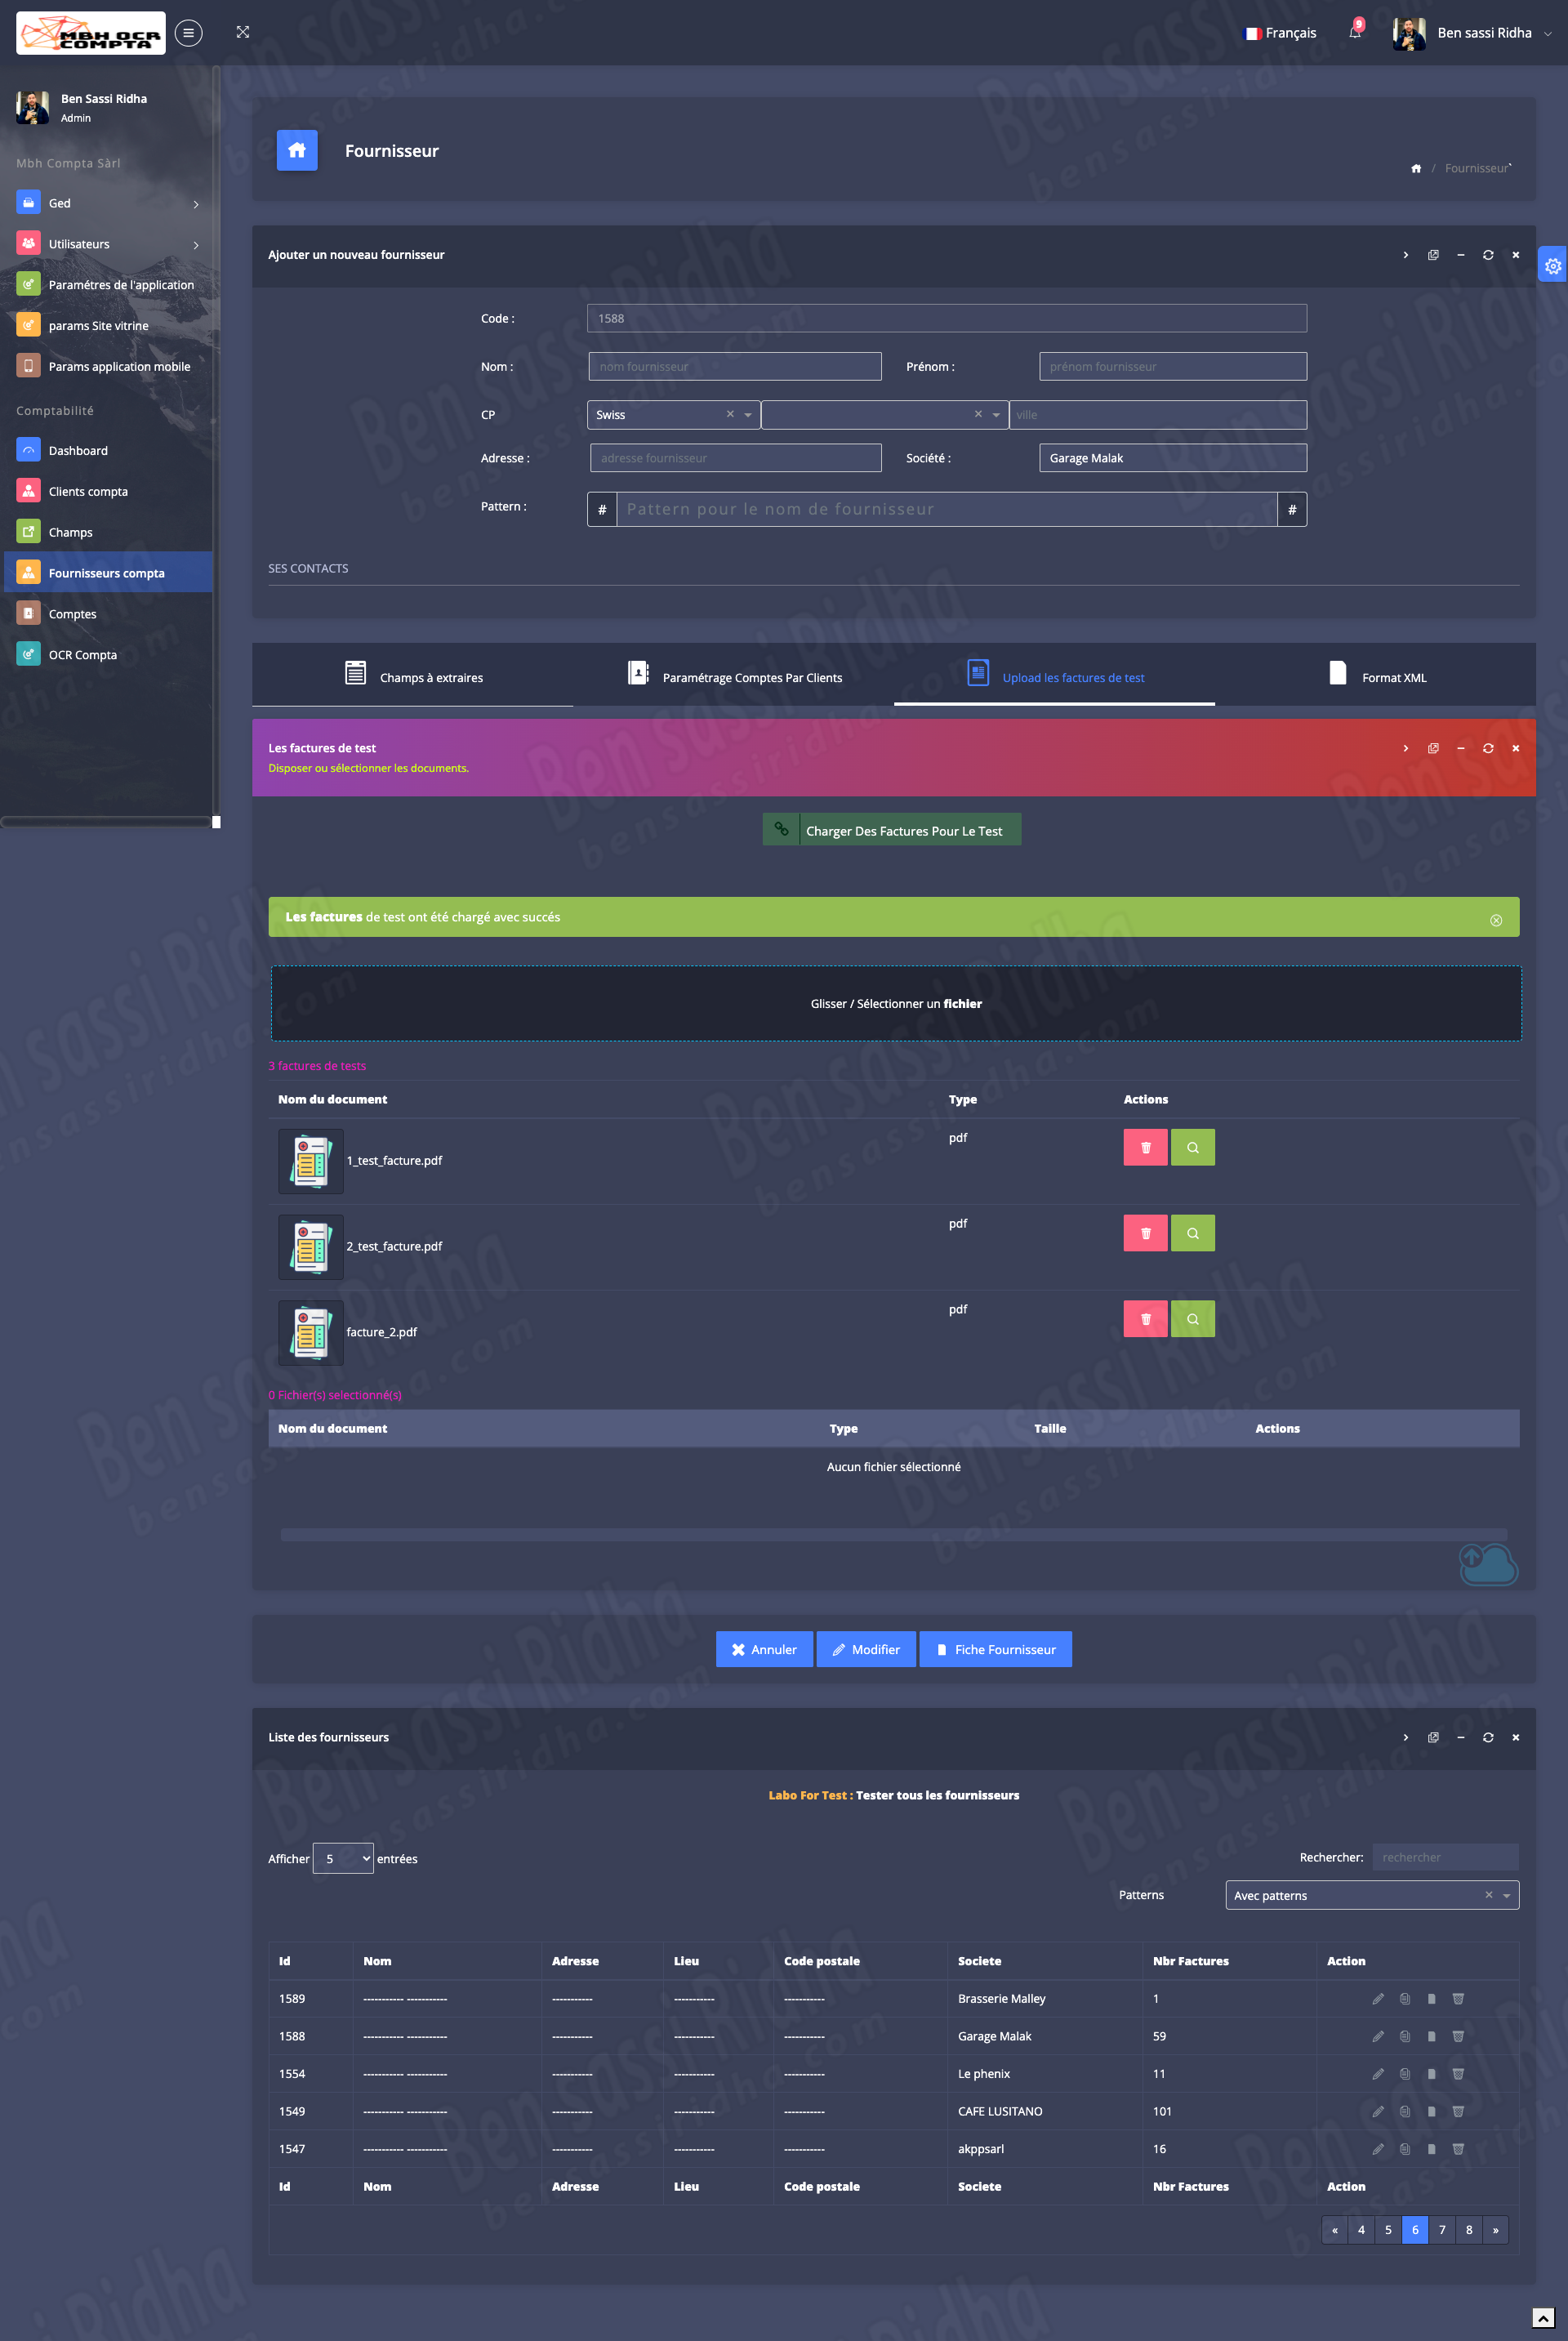
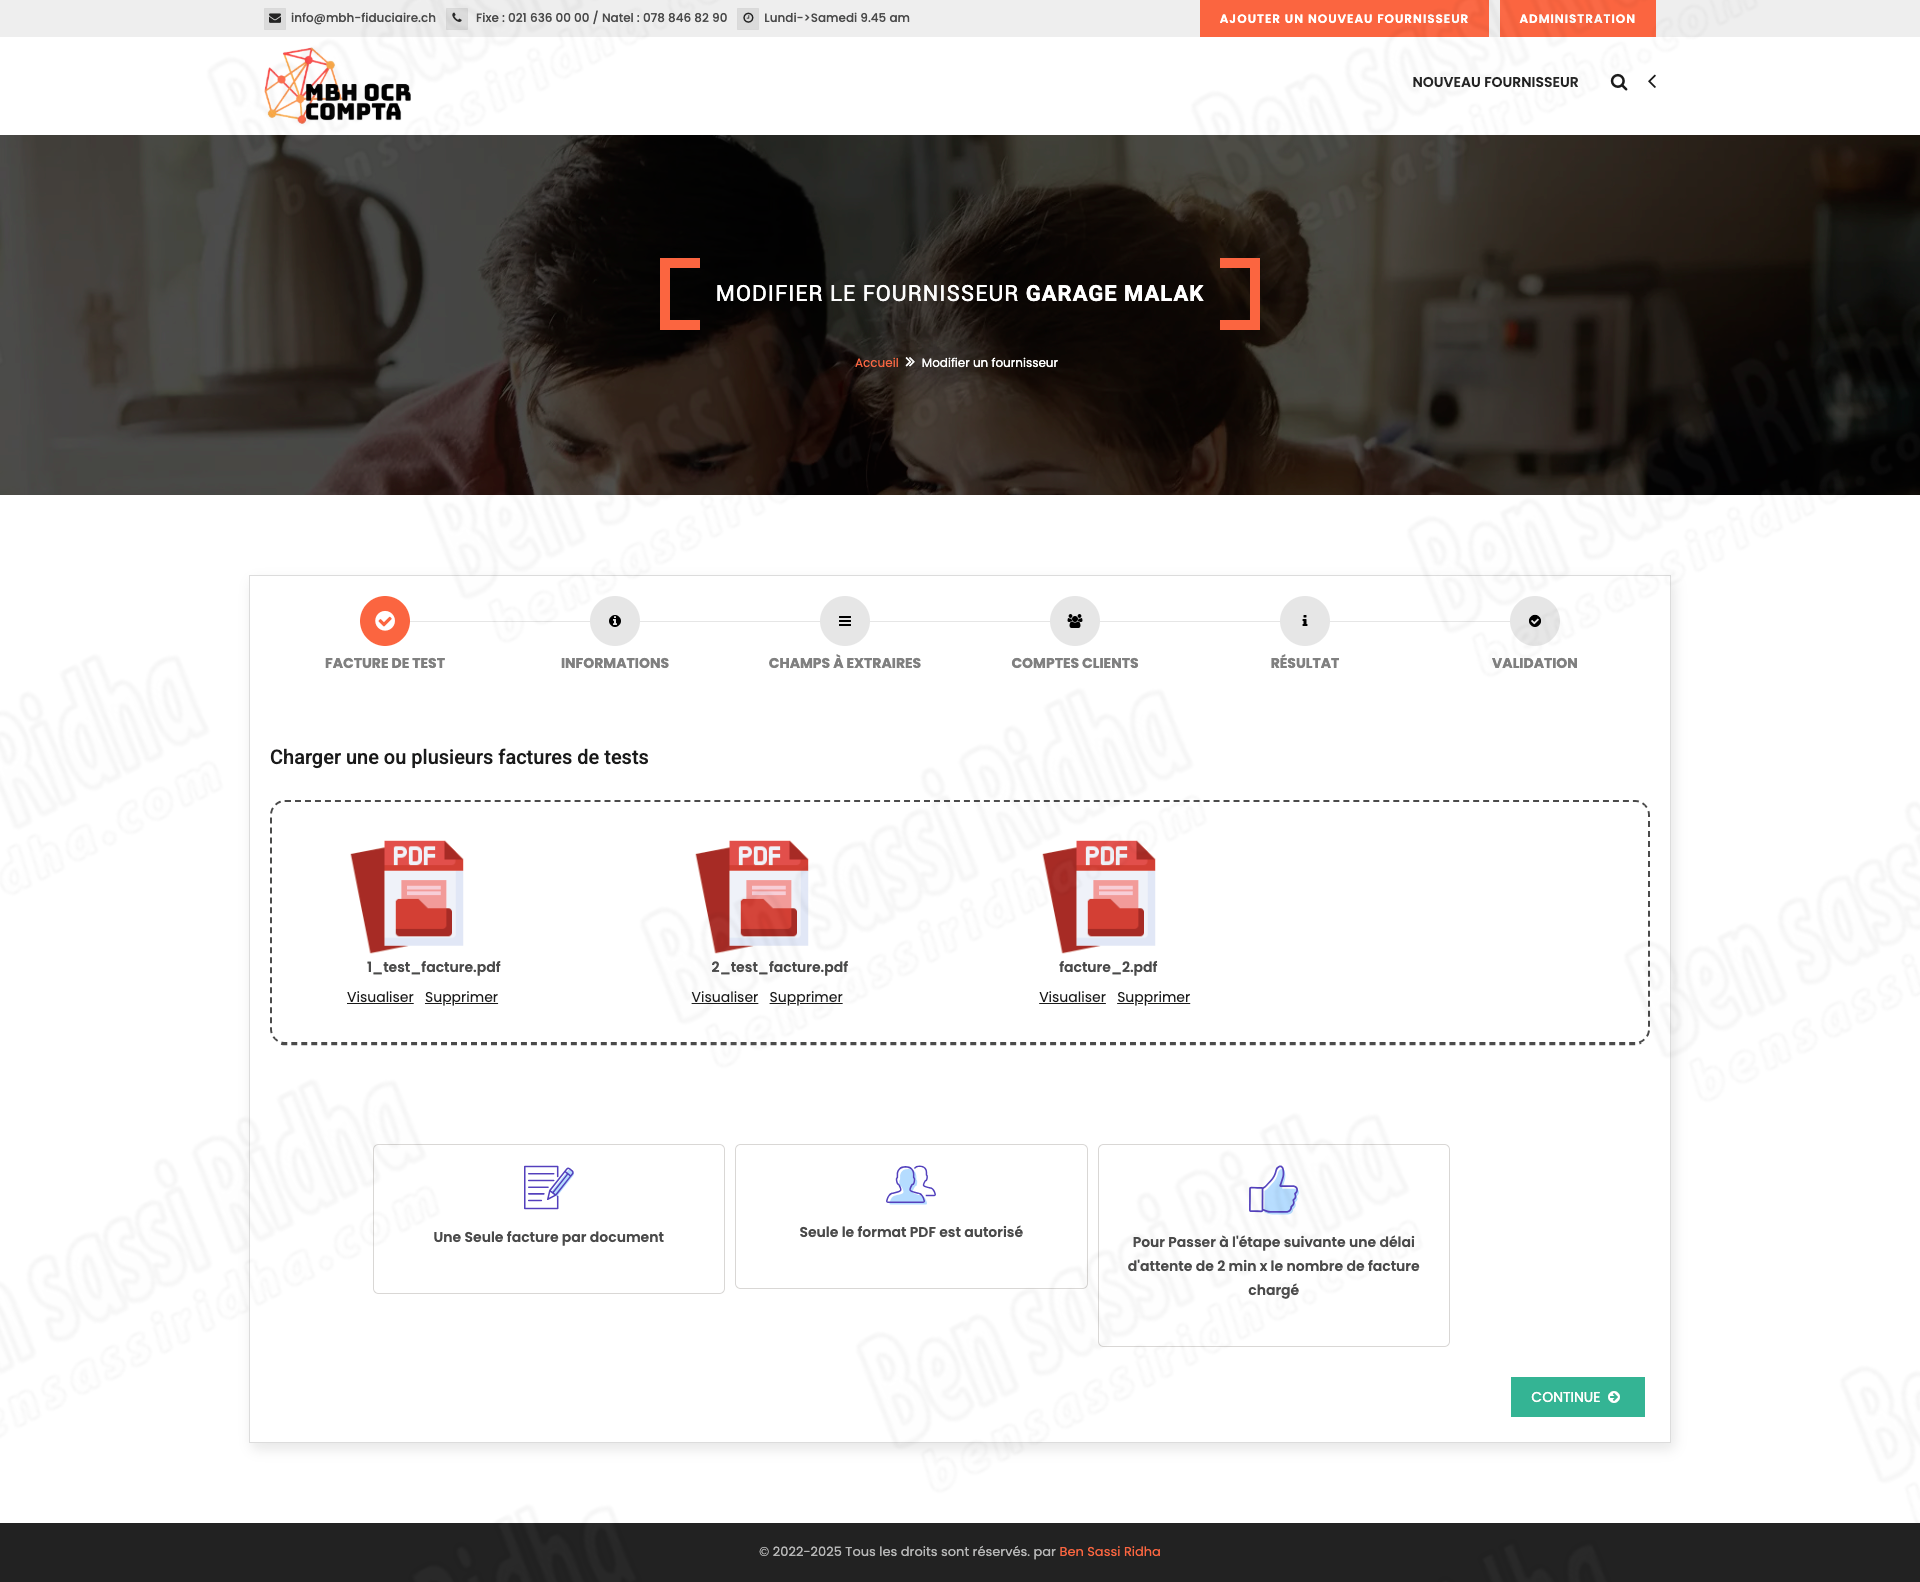
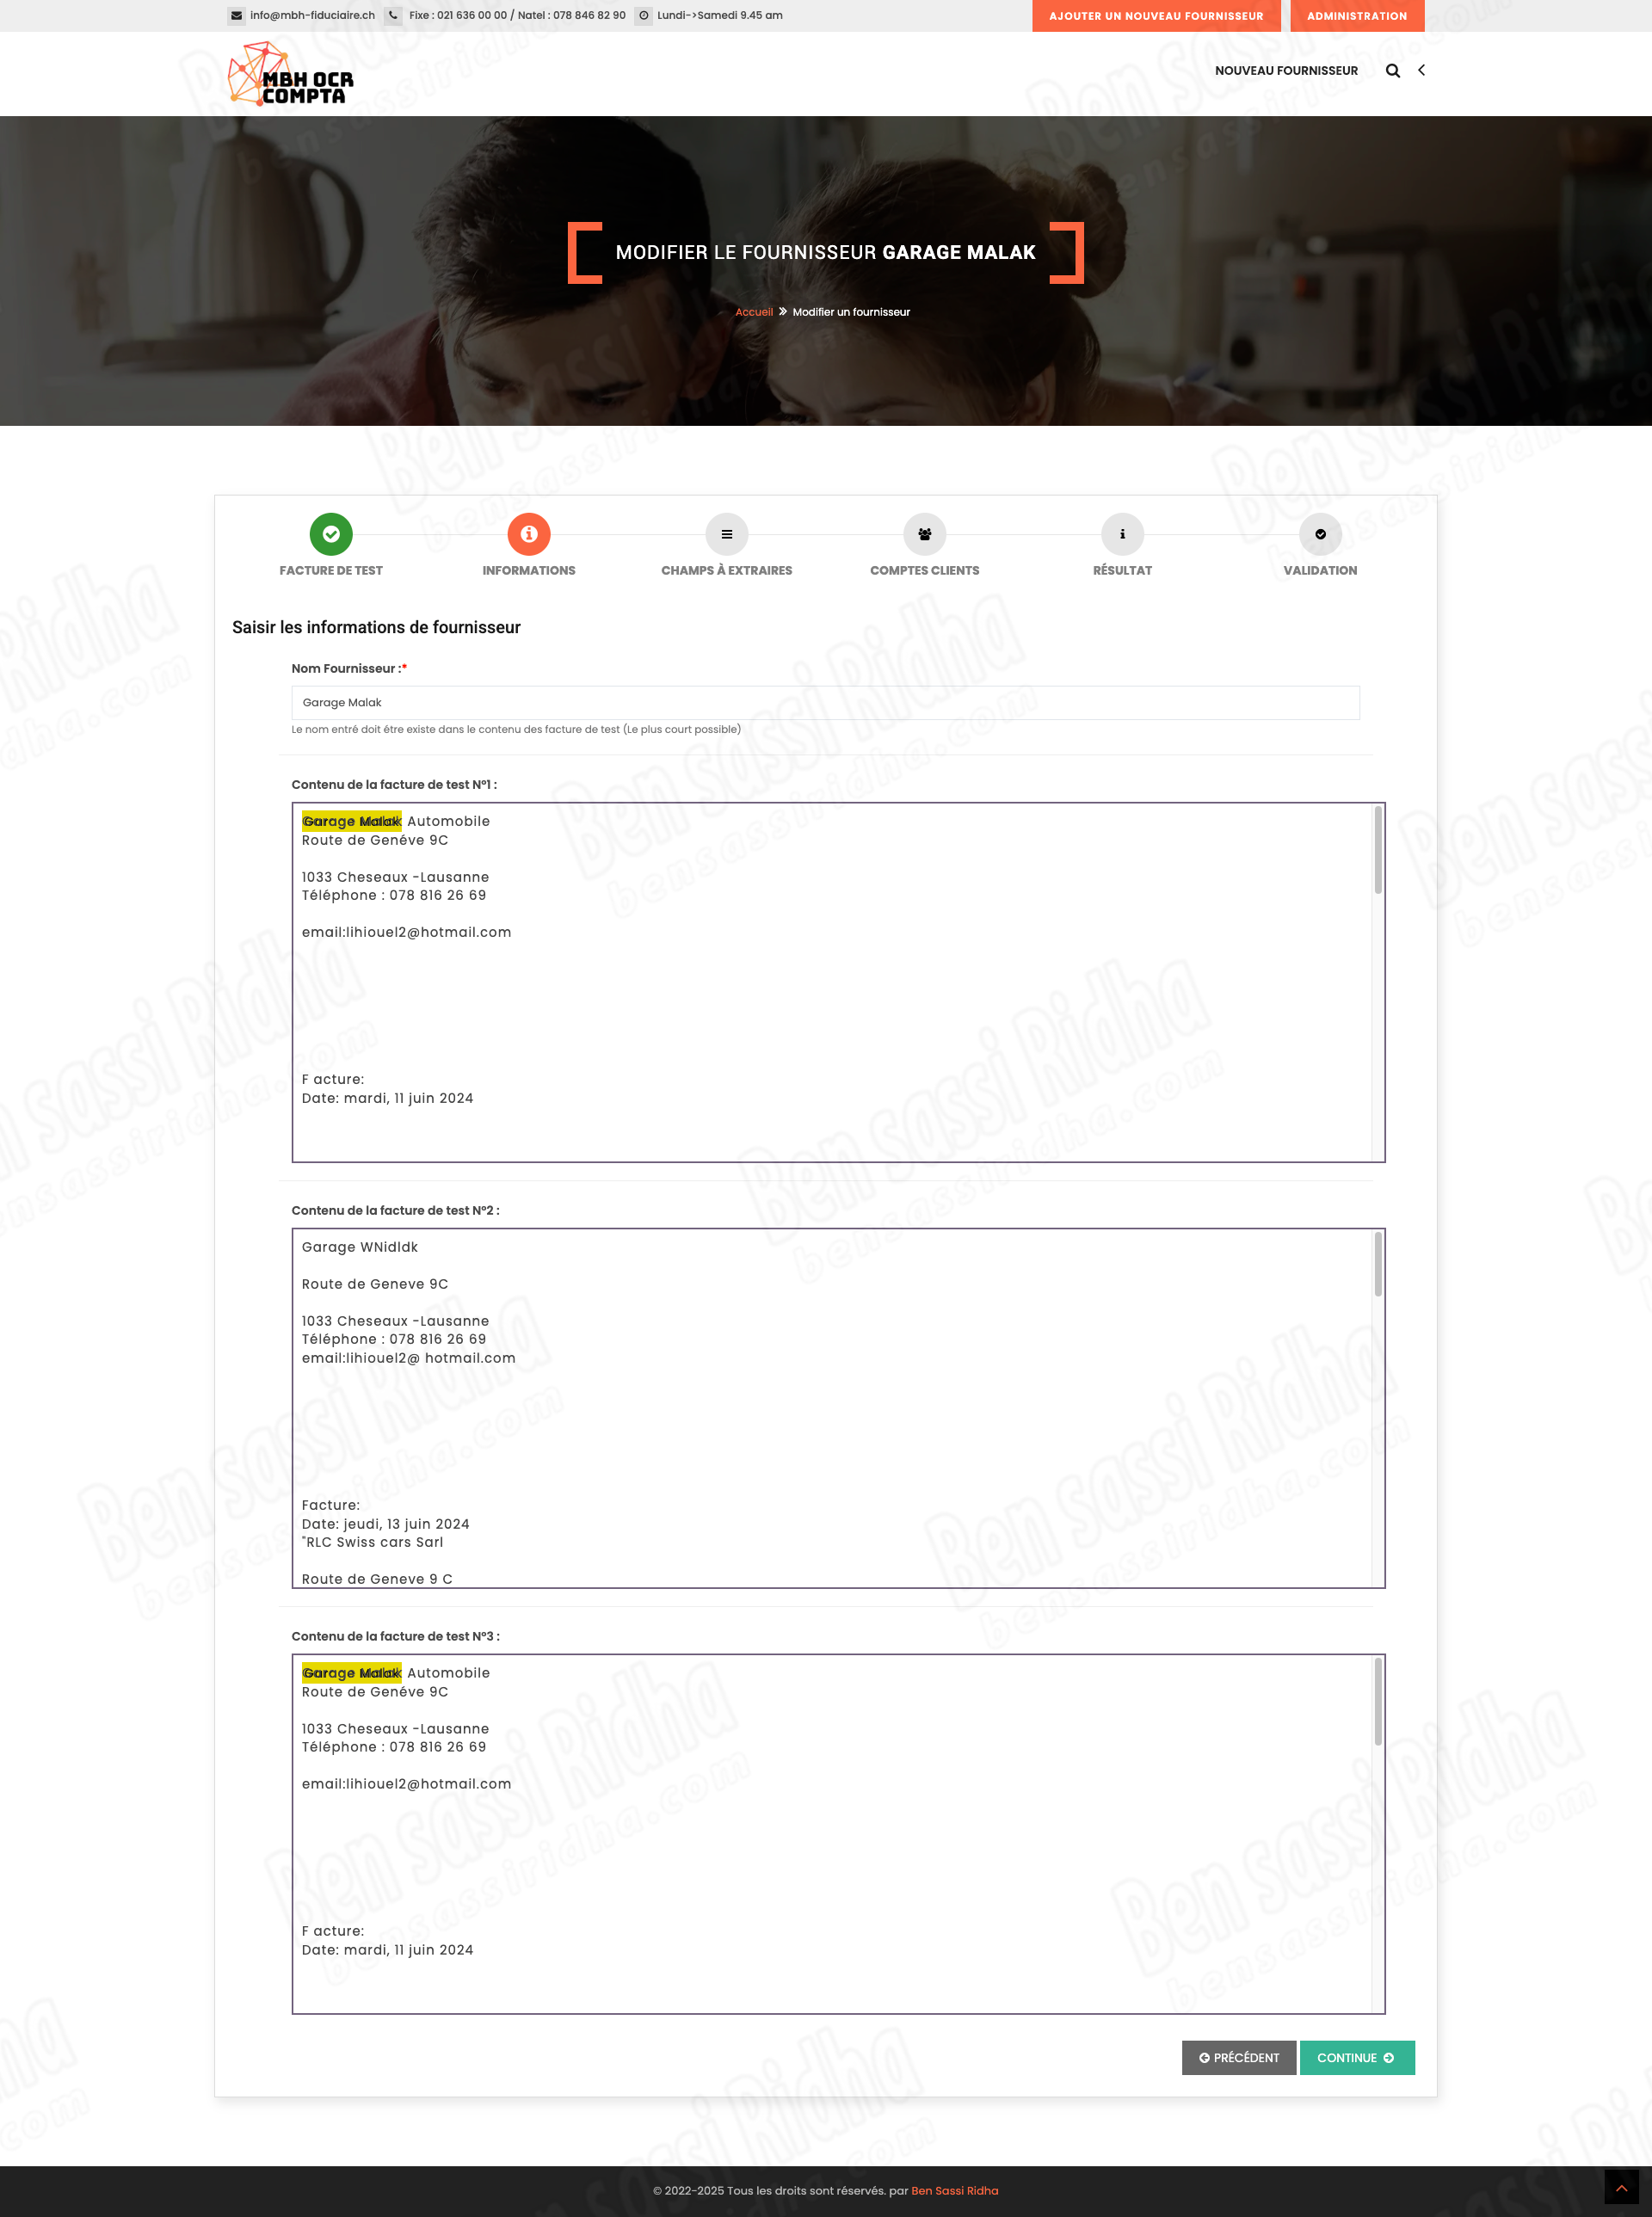
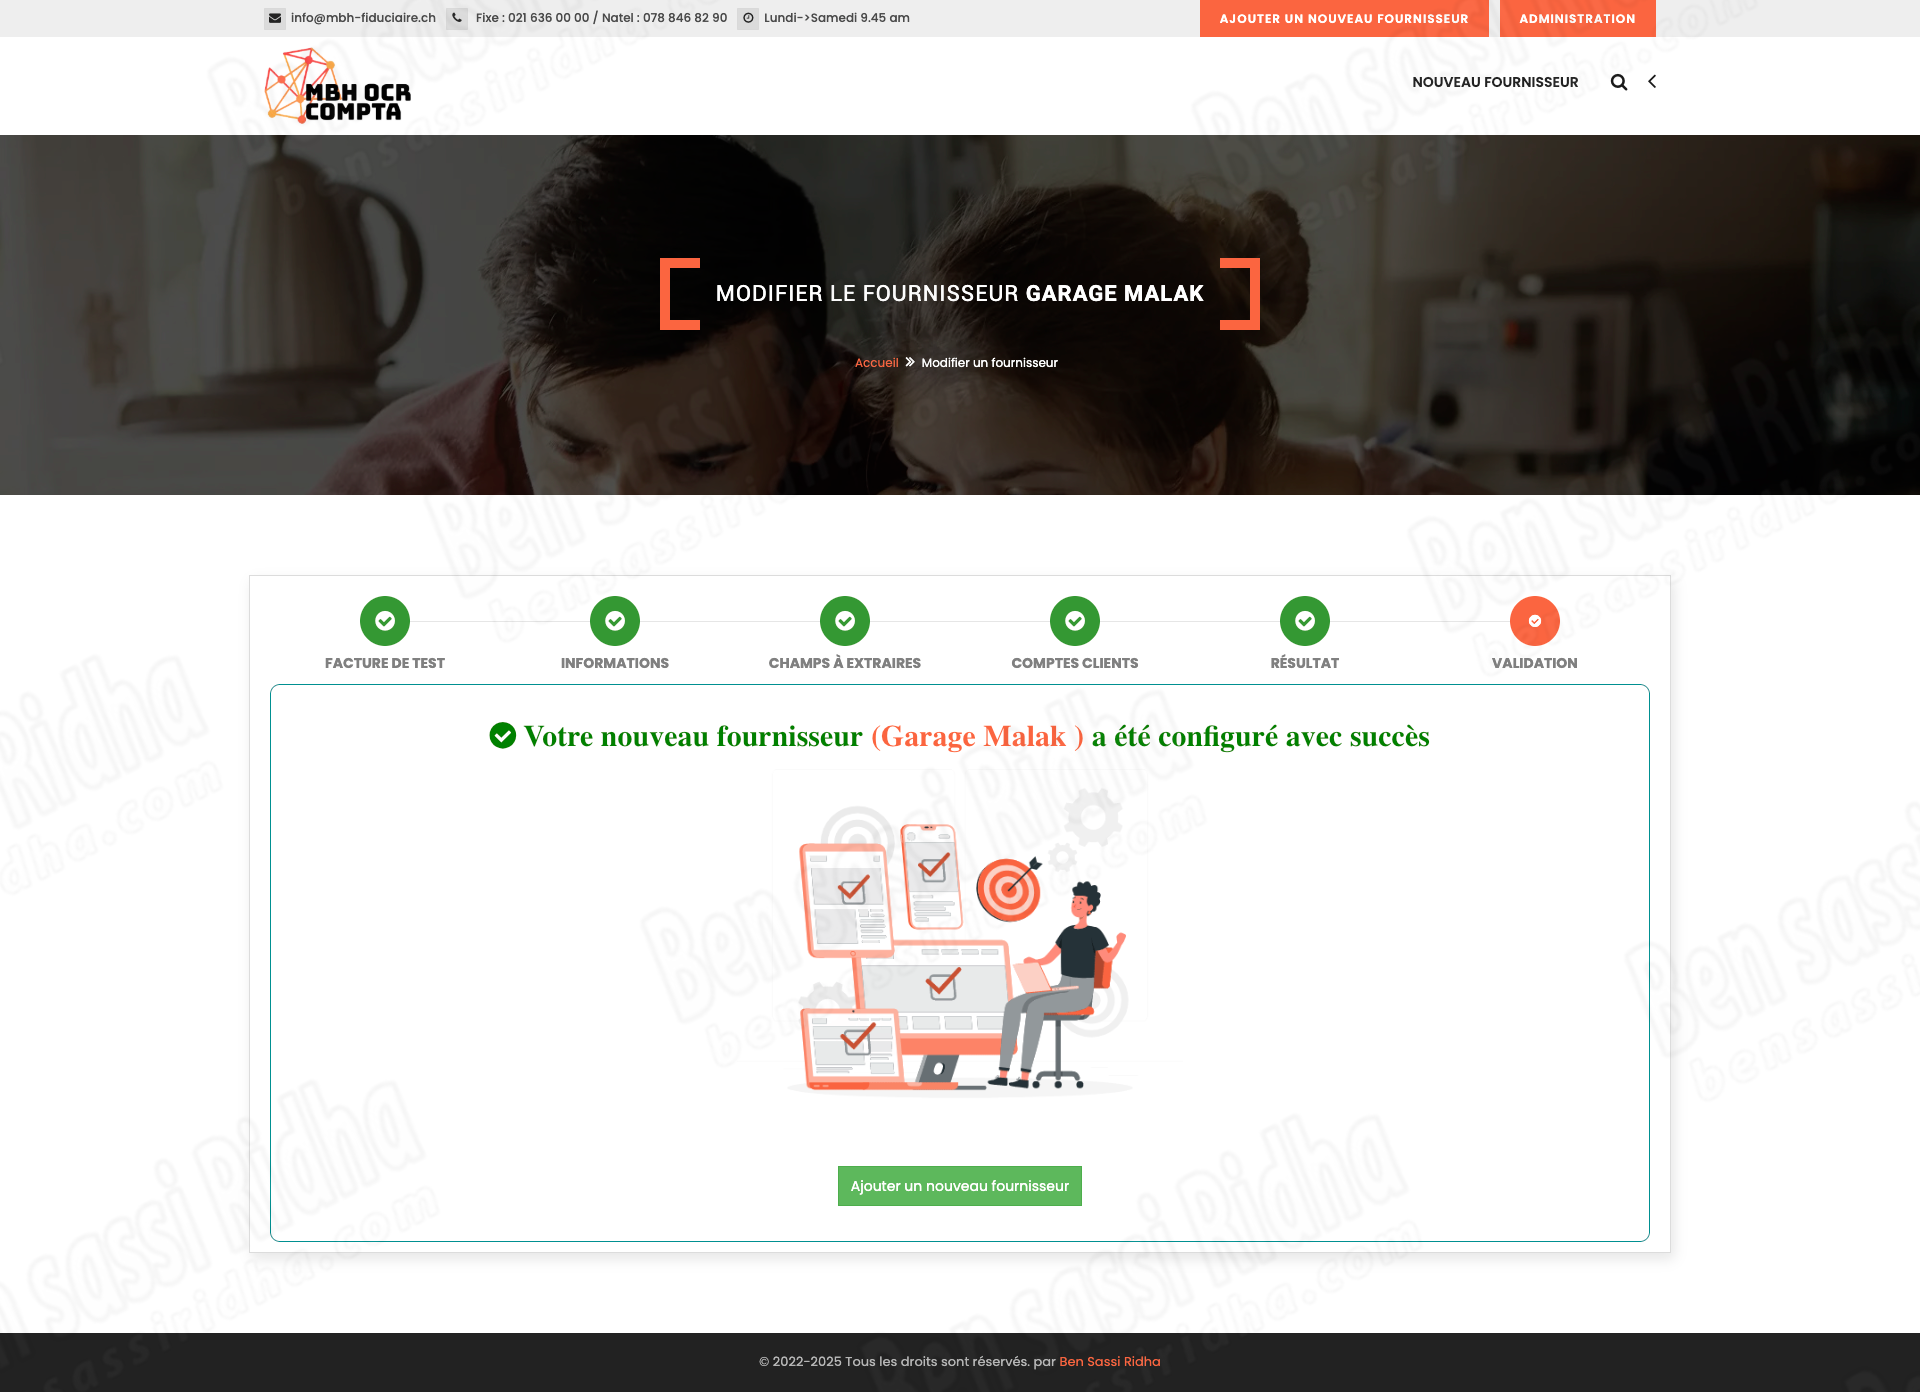
- Easily add a new supplier using an interface called ‘Test Lab’
- Frontend part to facilitate the addition of a new supplier with its model invoices as well as defining the patterns of each field to extract
Customers
This solution has been saled to several clients in Tunisia, Switzerland and France

Points on technologies
This project is composed of two parts, FrontEnd part developed by Angular 8 , VueJS 3.0 and a BackOffice part developed by Laravel 7. Communication between these two parts is ensured by web services
Pre Request Tools installed in OS
- Tesseract ocr 6
- ImageMagick
- Ghost Script
- LibTiff
Packages used on the Angular side
- Jselect
- JCalendar
- ngBootstrap
- ngx DataTable
- FullCalendar
- ngSnotify
- ngLightBox
- Moment
- Lodash
- ngxPermission
- ngxFavIcon
- ngxPagination
- ngxColorPicket
- ngxMask
Packages used on the Laravel side
- barryvdh/laravel-dompdf
- thiagoalessio/tesseract_ocr
- chumper/zipper
- kwn/number-to-words
- maatwebsite/excel
- ajcastro/eager-load-pivot-relations
- milon/barcode
- tymon/jwt-auth
Video Presentation
Version 3.0
OCR MBH – Version 3.0 Release Notes
Release Date: February 2026
Version: 3.0
🚀 Overview
OCR MBH v3.0 delivers major improvements in performance, scalability, and accuracy. This release introduces advanced queue management, supplier-driven extraction logic, batch processing, cluster execution, and infrastructure optimizations to support high-volume accounting document processing.
✨ New Features
ZED – Execution Queue System
Introduced ZED, a dedicated queue for storing and managing workbooks awaiting OCR execution.
Ensures controlled processing and improved execution stability.
Supplier Profile Management
Added a new interface to define and manage supplier profiles.
Centralizes supplier configuration and OCR-related metadata.
Advanced Pattern & Account Mapping
Introduced an advanced interface to define extraction patterns per supplier.
Enabled mapping of extracted fields to accounting accounts.
Added pattern testing on line items with preview of extraction results.
Supplier Filtering Enhancements
Added new filters in the supplier list:
Suppliers with defined patterns
Suppliers without patterns
Improves configuration tracking and setup efficiency.
Enhanced OCR Execution Engine
Added advanced field mapping during OCR execution.
Introduced flexible data cleanup options, including deletion rules.
Improved execution stability and data consistency.
Batch (Lot) Processing
Added batch processing to execute or modify multiple workbooks simultaneously.
Enables faster operations and bulk updates.
Image Comparison
Added image comparison functionality to visually verify OCR results against original documents.
Cluster Execution
Introduced cluster-based OCR execution to support large-scale processing.
Improves performance and throughput for high document volumes.
VPS & Infrastructure Improvements
Increased RAM capacity to support larger workloads.
Improved CPU utilization for better processing performance.
Enhanced overall system stability for continuous OCR execution.
🛠 Improvements & Optimizations
Improved system performance under heavy workload.
Optimized OCR execution pipeline for scalability.
Enhanced reliability for large workbook processing.
✅ Summary
OCR MBH v3.0 is a major upgrade focused on automation, scalability, and performance. With advanced supplier configuration, batch execution, and infrastructure enhancements, this version significantly improves operational efficiency and processing capacity.
Version 1.0
Clone to the GIT
https://gitlab.com/bensassi/nutriprocess.git
 English
 French